Picking a local model has become a filename problem. You find the model you want, open the files tab, and choose between a dozen builds whose names differ by a few characters: Q4_0, Q4_K_M, UD-Q4_K_XL, MXFP4_MOE. The names look like specifications. We read the tensor tables of eight builds of the same model to see whether they behave like specifications, and one of them contains none of the format its filename advertises. For a business pulling models onto staff machines, a wrong pick costs download time, disk and memory before anyone notices.
The model is Gemma 4 26B-A4B, a mixture-of-experts model with 128 experts and 8 active per token. We audited Google’s own release plus seven community builds carrying millions of downloads between them. No weights were downloaded. A GGUF keeps its header, metadata and complete tensor table at the front of the file, so a range request for the first 16 MB is enough to enumerate every tensor and its quantisation type. Eight builds cost about 128 MB of reading against roughly 140 GB of weights. Later audits used the same method on Qwen, GLM and Nemotron builds, and their results are folded in below.
Do community MoE GGUF builds have silent experts?
We started because of a warning that circulates whenever a large mixture-of-experts model gets community quants: that uneven compression leaves some experts effectively dead, while the model card still reports the original expert count. For a MoE model that would be serious. The router would keep sending tokens to experts that no longer hold useful weights.
We found no evidence of it in any of the eight builds.
Every one reports expert_count: 128 and expert_used_count: 8 in its metadata. More to the point, the expert weights in this architecture are fused: each layer holds one ffn_gate_up_exps tensor and one ffn_down_exps tensor, and the expert dimension is a dimension of that tensor. In all eight builds, across all 30 blocks, that dimension is 128. There is nowhere for a dropped expert to hide. A build that had quietly lost experts would show a smaller dimension than its metadata claims, and none does.
That is a negative result and it is worth publishing as one. The claim is repeated confidently and it did not survive contact with the files. Across fifteen mixture-of-experts builds in three model families, Gemma 4 26B-A4B, Qwen3.5-35B-A3B and the pruned builds below, the expert dimension of every fused tensor has matched the declared count. On a different architecture with 256 experts the answer was still no.
The reason is structural. Expert count is a number in the metadata and a dimension in a tensor, and the two have to agree or the file will not load. A quantiser cannot lose experts by accident, because the loader would reject the result.
Where experts really are removed: REAP-pruned builds
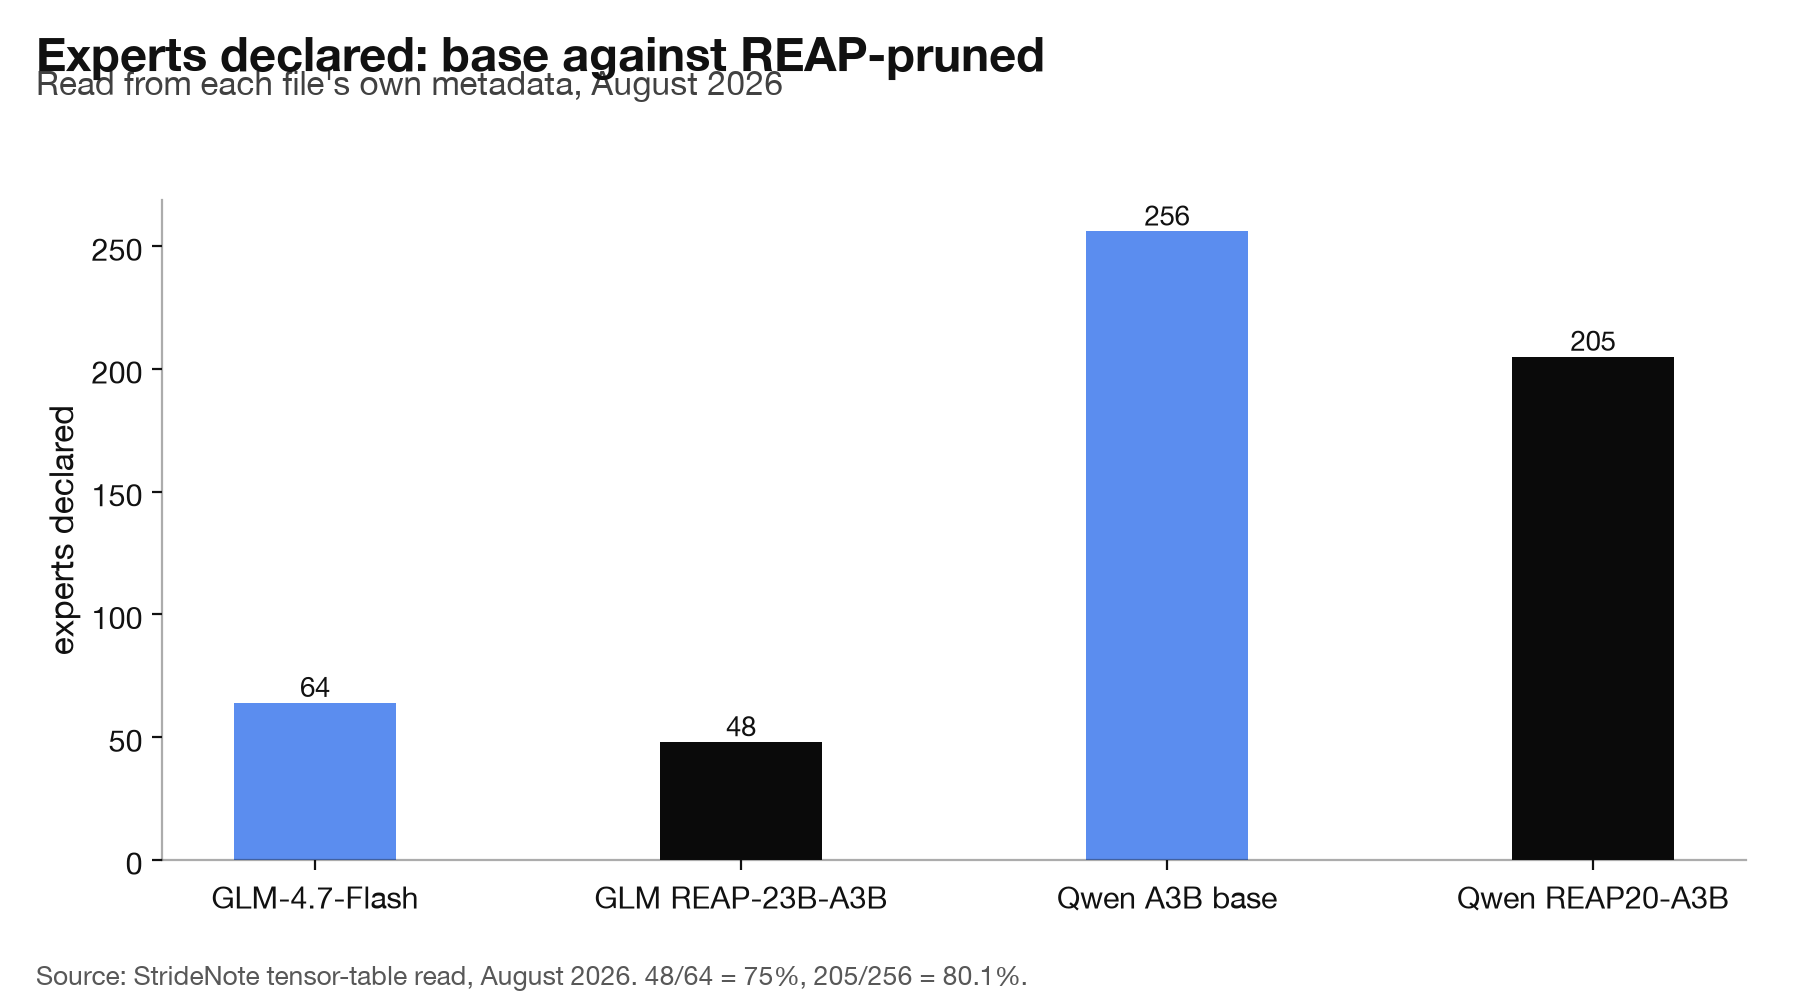
REAP is router-weighted expert activation pruning, published in October 2025. It ranks experts by how much the router activates them and deletes the ones at the bottom, before quantisation. What comes out is a smaller model with fewer experts, not a compressed version of the original. If any category of build were going to overstate its expert count, it would be this one. We read the tensor table and metadata of two REAP builds the same way, about 16 MB per file, and compared each with the model it came from.
| Build | Experts declared | Base model | Ratio |
|---|---|---|---|
| GLM-4.7-Flash-REAP-23B-A3B | 48 | GLM-4.7-Flash, 64 | 75% |
| Qwen3.6-28B-REAP20-A3B | 205 | Qwen3.x A3B, 256 | 80.1% |
The GLM build keeps 48 of 64 experts, a 25% prune. The Qwen build keeps 205 of 256, so 51 experts are gone, 19.9 percent, and its filename says REAP20. Both keep the same number of blocks as their base, 47 for GLM and 40 for Qwen, so the prune took experts out of layers rather than removing layers. Experts do go missing, but only when somebody means it, and the file says so in two places.
One detail for anyone auditing GLM builds: the architecture string in the metadata is deepseek2, not something GLM-specific. Architecture names in GGUF describe the implementation family a runtime should use, not the brand on the model card, and searching for the wrong string will make you think a file is missing.
Neither file carries a quality comparison against its base, and pruning is exactly the operation where you would want one. The paper reports results on the models it tested; the community builds inherit the method, not the measurements. A REAP build advertises a smaller total size, which looks like a quantisation win and is not: fewer experts means less capacity, the weights shrink but the active-parameter count per token may not, and the size comparison that matters is against the same expert count. We have not measured what pruning costs in output or saves in memory on a fixed task. That needs the same task set run through GLM-4.7-Flash and its REAP-23B build, and through the Qwen base and its REAP20 build, at the same quant level on our test machine, and it is on our list.
Why does a file named UD-Q4_K_XL contain no Q4_K?
unsloth’s gemma-4-26B-A4B-it-qat-GGUF repository offers a single build, gemma-4-26B-A4B-it-qat-UD-Q4_K_XL.gguf. The name follows a convention readers of quantised models know well: Q4_K is the K-quant family, and the XL suffix marks the most generous mix in that family.
The file contains 266 Q4_0 tensors and 392 F32 tensors. There is not a single Q4_K tensor in it. No Q5_K, no Q6_K either.
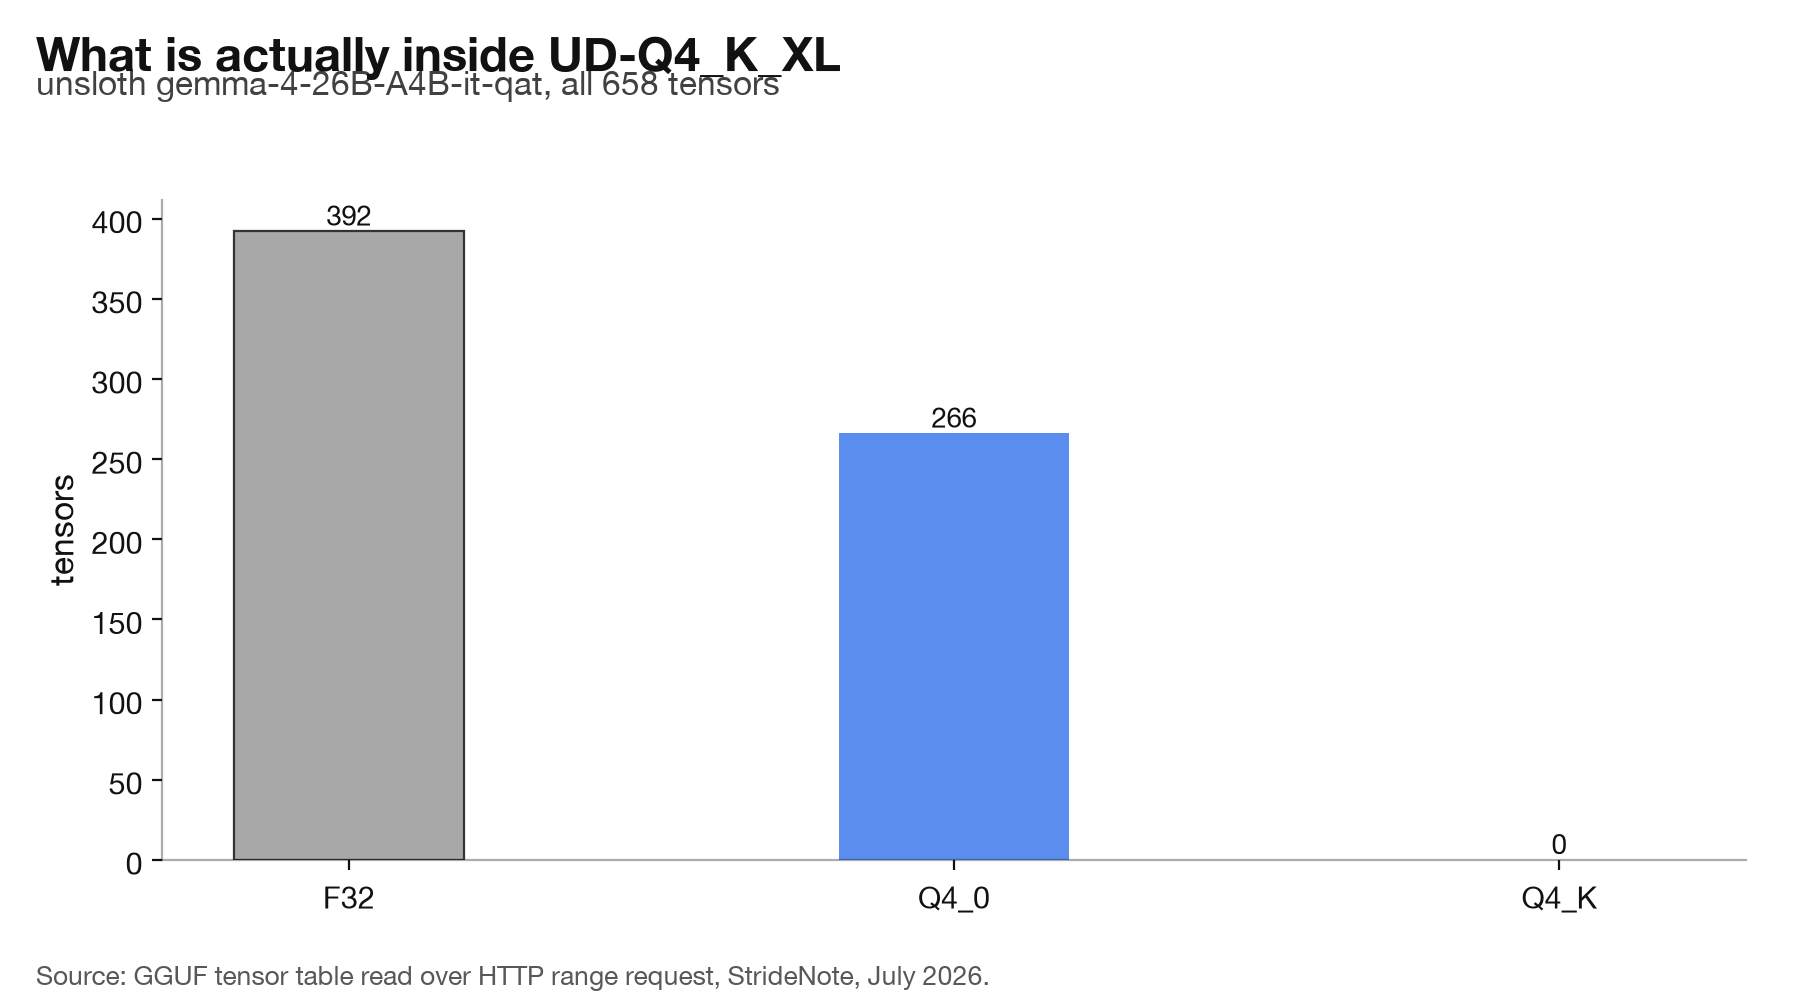
The file is not lying about itself. Read its metadata and it is candid: general.file_type is 2, which is Q4_0, and general.name reads “Gemma-4 26B-A4B IT (smart Q4_0, QAT-lossless)”. That is an accurate description. This is a quantisation-aware-trained model, so shipping it as Q4_0 rather than converting it to a K-quant mix is a defensible choice, arguably the correct one.
The gap is between the metadata and the filename. The metadata says Q4_0 and the filename says Q4_K_XL, and the filename is what appears in a download list, a model picker, and every guide that tells you which file to pull. Anyone selecting on the name is selecting on something the file does not claim about itself.
Two Unsloth UD names, one Nemotron file
The same gap turned up at the low end of Unsloth’s Nemotron 3.5 Lightning list, which runs to nineteen files. UD-IQ1_M and UD-IQ2_XXS are both 19,429,059,648 bytes, the same integer in the Hugging Face blob index. We read both tensor tables over range requests and compared all 417 tensors by name, shape and quantisation type. The number that differ is zero. The only changed field is general.file_type: 31 in UD-IQ1_M and 19 in UD-IQ2_XXS, which include/llama.h in llama.cpp maps to LLAMA_FTYPE_MOSTLY_IQ1_M and LLAMA_FTYPE_MOSTLY_IQ2_XXS. Eight megabytes of reading settled it against files of roughly 19.4 GB each.
The third file in that size cluster, UD-IQ2_M, is 19,432,070,208 bytes, 3,010,560 bytes heavier. It differs from UD-IQ1_M in exactly 14 of 417 tensors: the attn_k and attn_v weights of the model’s seven attention layers, promoted from Q5_1 to Q8_0. The other 403 are the same. The two files differ by 0.015 percent of their size. The type histogram of UD-IQ1_M, which is also that of UD-IQ2_XXS:
| Tensor type | Count |
|---|---|
| F32 | 243 |
| Q8_0 | 49 |
| Q5_1 | 46 |
| IQ4_NL | 46 |
| Q6_K | 23 |
| Q5_K | 7 |
| Q5_0 | 2 |
| BF16 | 1 |
There is no IQ1 tensor in the file named IQ1_M, and no IQ2 tensor in the files named IQ2_XXS or IQ2_M. The expert weights, by our arithmetic about 92 percent of this build’s bulk, are IQ4_NL in all three. Unsloth’s Dynamic method is explicitly mixed-precision, and on a model whose architecture puts only seven attention layers among 53 blocks and hangs almost all its weight on 128-expert MoE blocks, protecting 14 attention tensors is a sensible allocation. The label is the problem: a name from the llama.cpp file-type enum describes a uniform quantisation the file does not use, so it becomes a rung on a ladder rather than a description.
The collapse is not universal. As a control we read UD-IQ3_XXS from the same repository: 19,758,307,392 bytes, general.file_type 23 for LLAMA_FTYPE_MOSTLY_IQ3_XXS, and a tensor table that genuinely differs from the other three. The rungs separate further up. At the bottom of this list, three names compress into two builds, which is where a reader on a tight memory budget is most likely to be looking. We have not measured what the 14 promoted attention tensors change in output; that needs UD-IQ1_M and UD-IQ2_M run against a fixed prompt set on our test machine, and it is on our list.
How much do GGUF builds of the same model differ?
Enough that “the same quant” is not a useful phrase.
Four of the eight builds are nominally the same thing: the Q4_0 QAT release. They differ anyway, in the small number of tensors each quantiser decides to protect at higher precision.
| Build | Body tensors | Promoted tensor |
|---|---|---|
| google (official) | 205 Q4_0 | 1 at Q6_K |
| lmstudio-community | 205 Q4_0 | 1 at Q6_K |
| ggml-org | 205 Q4_0 | 1 at Q8_0 |
| unsloth UD-Q4_K_XL | 206 Q4_0 | none |
Three organisations, three answers, on a file they all describe the same way.
Widen to all eight and the expert tensors diverge further. Every build handles the two expert tensor classes separately, and almost none handles them the same way:
| Build | ffn_gate_up_exps | ffn_down_exps |
|---|---|---|
| google, lmstudio-community, ggml-org, unsloth UD | Q4_0 | Q4_0 |
| unsloth MXFP4_MOE | MXFP4 | Q5_1 |
| AtomicChat Q4_K_M | Q4_K | Q5_0 and Q8_0 |
| AtomicChat Q2_K | Q2_K | Q4_0 |
| bartowski IQ2_XXS | IQ2_XXS | IQ4_NL |
Two patterns stand out. AtomicChat’s Q4_K_M does not use one type for ffn_down_exps; it promotes 14 specific layers to Q8_0 (blocks 0, 1, 2, 5, 8, 11, 14, 17, 20, 23, 26, 27, 28, 29) and leaves the other 16 at Q5_0. That is first three, last four, and roughly every third block in between: a fixed schedule rather than a scatter.
And quantisers disagree about which end of the network to protect. unsloth’s MXFP4 build promotes the final block, 29, in both expert classes. bartowski’s IQ2_XXS build promotes the first block, 0. Same architecture, opposite instincts.
The spread in how many distinct quantisation types a build uses is the cleanest summary:
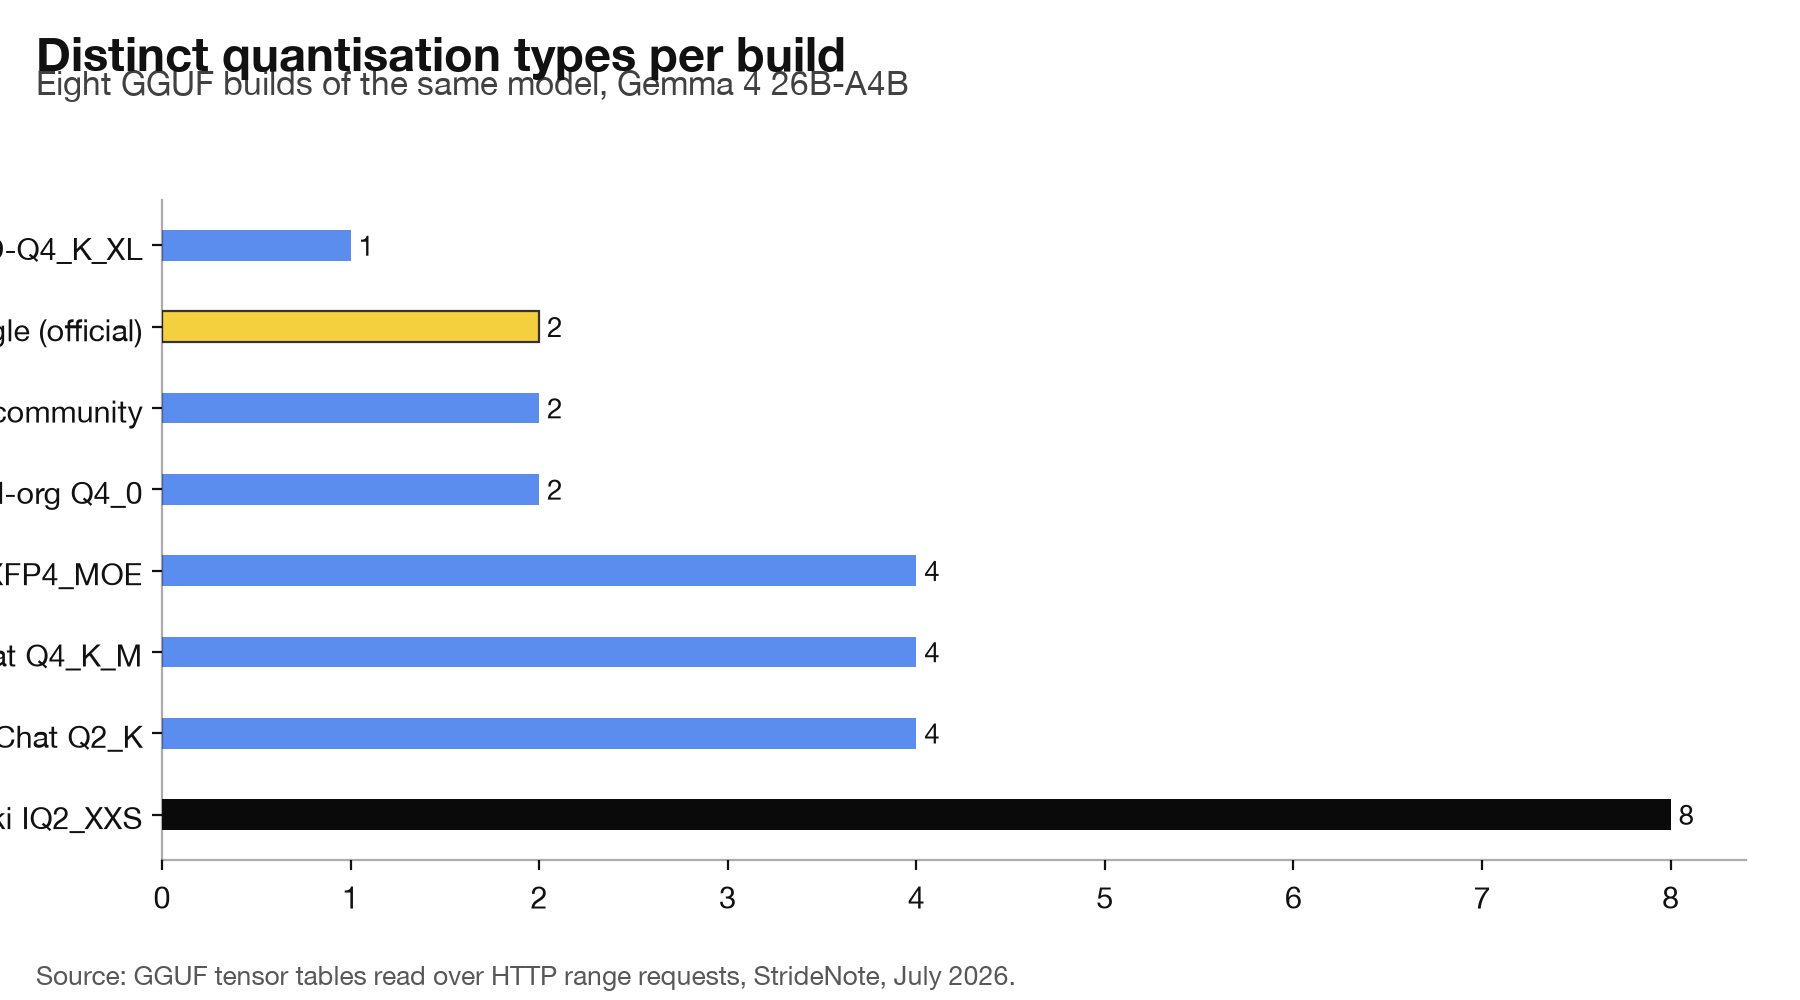
None of this is misconduct. Every one of these choices is a reasonable engineering decision. The point is narrower: the filename compresses all of it into a label, and the label is doing work it cannot support. Our own NVFP4 vs Q4_K_M piece ran into the same wall from the other direction, where a nominally 4.5-bit format shipped at 5.43 to 5.60 bits per weight because conversion was partial by design.
The layer schedule is mostly one line of llama.cpp
We first read the promotion patterns as a policy each publisher decides independently. Having compared fifteen builds side by side, that was wrong in the case that matters most. The rule lives in src/llama-quant.cpp:
auto use_more_bits = [](int i_layer, int n_layers) -> bool {
    return i_layer < n_layers/8 || i_layer >= 7*n_layers/8 || (i_layer - n_layers/8)%3 == 2;
};
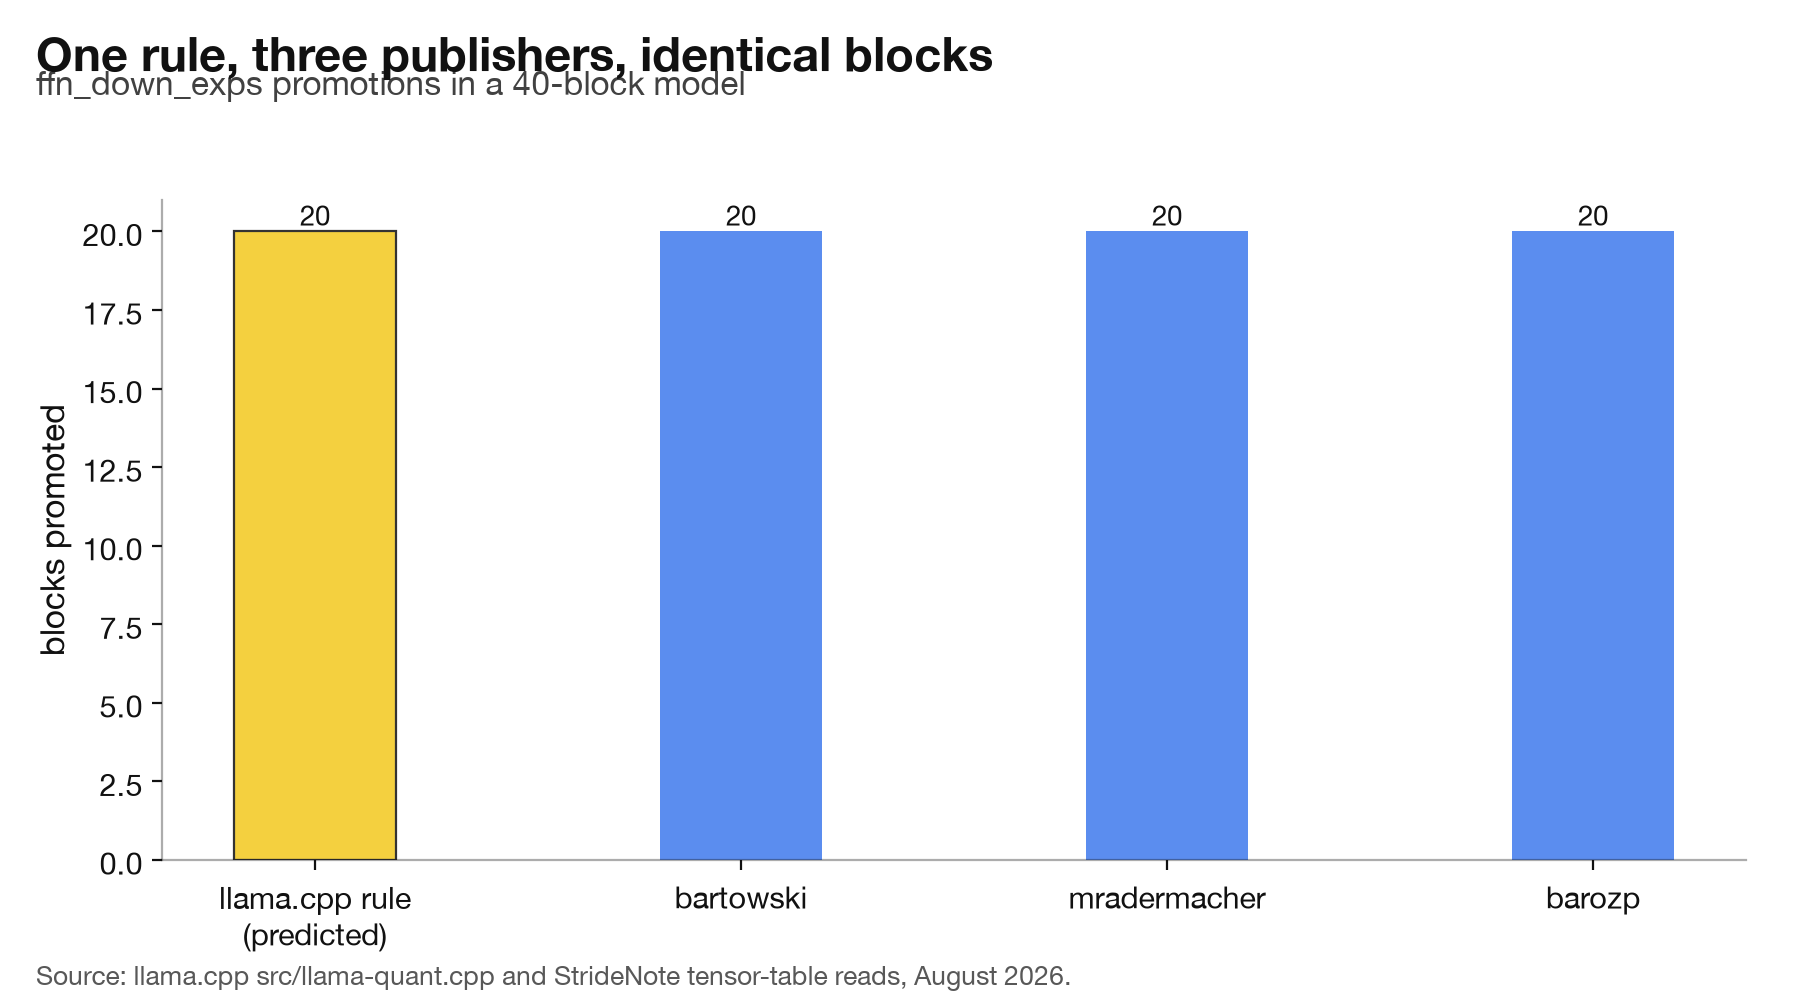
A layer is promoted if it is in the first eighth of the network, or the last eighth, or on every third layer counting from the end of that first eighth. The function decides whether a tensor gets Q6_K instead of Q5_K, Q5_K instead of Q4_K, and so on. For a forty-block model it selects twenty layers: 0 to 4, then 7, 10, 13 and onward in threes, then 35 to 39. We set the measured ffn_down_exps promotions of three Qwen builds against that prediction:
| Build | Publisher | Promoted blocks |
|---|---|---|
| Qwen3.5-35B-A3B IQ3_M | bartowski | matches |
| Qwen3.5-35B-A3B heretic Q4_K_M | mradermacher | matches |
| Qwen3.6-28B-REAP20-A3B Q4_K_M | barozp | matches |
All three leave the same twenty blocks at the lower type, beginning 5, 6, 8, 9, 11, 12, which is the set the rule predicts. Three publishers, two base models, one of them expert-pruned, and the schedule is identical. Llama 4 Scout, at forty-eight blocks, also lands on the rule’s selection. Because the rule is computed from n_layers, it produces a different set for every depth and still matches. The surrounding code also uses it for attention value projections and feed-forward down projections, and in one branch only when a model has exactly eight experts, so the schedule you see depends on architecture as well as depth.
One case does not match. The GLM-4.7-Flash builds have forty-seven blocks, and their measured pattern begins 1, 2, 3, 4, 7, 10. The rule’s first group starts at block 0, which is absent. Our audit classifies a layer as an outlier relative to the most common type in its class, so a build where block 0 received a third, higher type would show exactly this. That is plausible and unconfirmed, so we do not count GLM as a match. The genuine exceptions are the informative ones: unsloth’s MXFP4 build of Qwen3.5 promotes a single block, number 10, which no reading of the rule produces, and bartowski’s builds promote block 40, which is the multi-token prediction head rather than a normal layer.
So a large part of the spread above is the same default responding to different quant levels and block counts. Publishers diverge in which quant level they target; within a level, the layer schedule is mostly inherited. It also answers who chooses which tensors the _M suffix promotes: on the common path, nobody chooses per model.
How do you check a GGUF before you download it?
The method costs about 16 MB per file and needs no special tooling.
A GGUF starts with the magic bytes GGUF, a version, a tensor count and a metadata count, followed by the metadata key-value pairs and then one record per tensor giving its name, shape, quantisation type and offset. All of it sits before the weights. An HTTP range request for the first chunk of the file gets you the entire table.
Start with exact byte sizes from the Hugging Face blob index rather than the rounded figures in the web view: two files with the identical integer are almost certainly the same build. Then read the table:
general.file_typeandgeneral.name. These often describe the file more honestly than its filename does.- The type histogram. Count tensors by quantisation type. A file whose name promises a K-quant mix and whose histogram shows none is telling you something.
- For a MoE model, the expert tensors. Confirm the fused expert tensors carry the expert count the metadata advertises, per layer, across every block, and check what type they use, because they carry most of the bits and a quant level that leaves them untouched has barely changed the file.
- The layer promotions. A build that follows the llama.cpp schedule was made with standard tooling and settings. A deviation, such as a single-block promotion or a preserved draft head, is where somebody made a decision worth understanding.
One trap, because we fell into it. The tensor type is stored as an integer, and we mapped those integers from memory on the first pass. We had 39 as NVFP4, which made unsloth’s MXFP4 build look as though it contained no MXFP4. Checking llama.cpp’s ggml.h shows 39 is MXFP4 and 40 is NVFP4. The filename was accurate and our table was not. Read the enum from the source before drawing a conclusion from it. The same enum puts Q1_0 at 41, which confirms the type-41 tensors we found in the Bonsai 27B teardown.
If you are choosing between builds of a model you intend to rely on, and especially a mixture-of-experts model where the experts dominate the weights, spend the 16 MB. The tensor table answers in seconds what the filename only gestures at, and on current evidence the two do not always agree.
What should a team check before it downloads a GGUF model?
A wrong build is rarely broken. It loads, it answers, and it costs more than it should in ways the filename does not show. Across our audits the measured cost of picking on the name alone has ranged from a few hundred megabytes to more than the memory of the machine:
| What the name hid | Measured cost | Where we found it |
|---|---|---|
| Two Kimi K3 builds with the same 2-bit label | 58 GB apart on disk | Kimi K3 build sizes |
| A multi-token prediction head kept at BF16 in a 4-bit Nemotron file | 2.67 GB of download and memory | Nemotron 3.5 Lightning GGUF |
| Two Unsloth quant names that are one file | 19.4 GB downloaded twice for the same bytes | The Nemotron UD names, above |
| An unquantised vision file beside a 4-bit model | 0.38 GB more than the 8-bit alternative | the mmproj GGUF file |
| Context memory the model manager does not show | 3.12 to 6.39 GB above the listed size | context window RAM |
The duplicate pair is exact arithmetic: a team that mirrors both UD-IQ1_M and UD-IQ2_XXS holds 38,858,119,296 bytes, about 38.9 GB, for one build, and pulls the extra 19.4 GB again every time a new machine takes the pair. The checklist that catches all five takes a few minutes per build and one person can run it before a model goes on an approved list:
- Read
general.file_type,general.nameand the tensor type histogram from the first 16 MB of the file, as described above. - Compare exact byte sizes, and record two names on one file as a single entry under both names.
- Sum the size of every shard from its headers and confirm the shard count matches the filenames, since a paginated listing can drop shards.
- Look for
nextntensors. If staff will not use speculative decoding, a build without the prediction head is the smaller download. - For a vision model, add the mmproj file to the total and choose its precision on purpose.
- Add the context you plan to use to the file size. On Gemma 4 31B we measured 80 KB per token.
- Record a pruned build as a separate model, with its expert count, so nobody later reads the smaller file as a cheaper copy of the same thing.
- Record the exact repository and filename on the approved list, so every machine pulls the same build.
The last item matters as much as the rest. Two staff who each pick “the Q4_K_M” from different publishers can end up running different files with different memory needs, and any comparison between their results is then a comparison of builds rather than of the model. At one quant level the layer schedule is not a reason to prefer one publisher, since the three Qwen builds above share it; the deviations are. Whether a team gets the same schedule by quantising the model itself we have not tested. We have not quantised Qwen3.5-35B-A3B with default llama.cpp settings and compared its tensor table and output with the publisher builds, and that job is on our list. What quantising in-house does give a team is the record of which source weights went in and which llama.cpp version ran.
Summing shards the same way showed the smallest Kimi K3 build is 589 GB. The vision half of a GGUF follows different rules again, which is what the mmproj GGUF file actually holds covers.