The question people ask is “what is the best local model right now,” and the honest answer is that the question is shaped wrong. There is no single best model, the same way there is no single best vehicle. The right model is decided by two things the leaderboards leave out: how much RAM you have, and what you actually want the model to do. Get those two right and the choice almost makes itself. For a business, the job is usually a specific task, such as drafting support replies or summarising long documents, and the speed of that task on your hardware is what staff will feel.
So we are going to organise this the way the decision actually works. First by what you have, then by what you want. We will name real model families in general terms, and we will not quote leaderboard numbers, because the numbers move monthly and the principle does not.
The answer to the question underneath, whether a local model is good enough to use every day, is yes for ordinary work. For support replies specifically, our free and paid AI for customer support test shows what a local model got right and wrong on 30 real-shaped emails.
How do you choose a local LLM?
A local model lives in memory. If it does not fit, it does not run. If it barely fits, it swaps to disk, crawls, and pushes your editor and browser out of memory while it works. So the first filter is not quality, it is fit.
The Atlas note on Ollama puts the practical floor at 16GB of RAM recommended and 8GB as a minimum for small models. That is your starting map. A bigger model is generally more capable, but a model that overruns your memory is not more capable to you, it is just slow. The single most common mistake we see is people reaching for the largest model they can name and then wondering why the machine stutters. Leave headroom. The model has to share the machine with everything else you have open.
So before anything else: know your RAM, and pick from the tier that fits with room to spare.
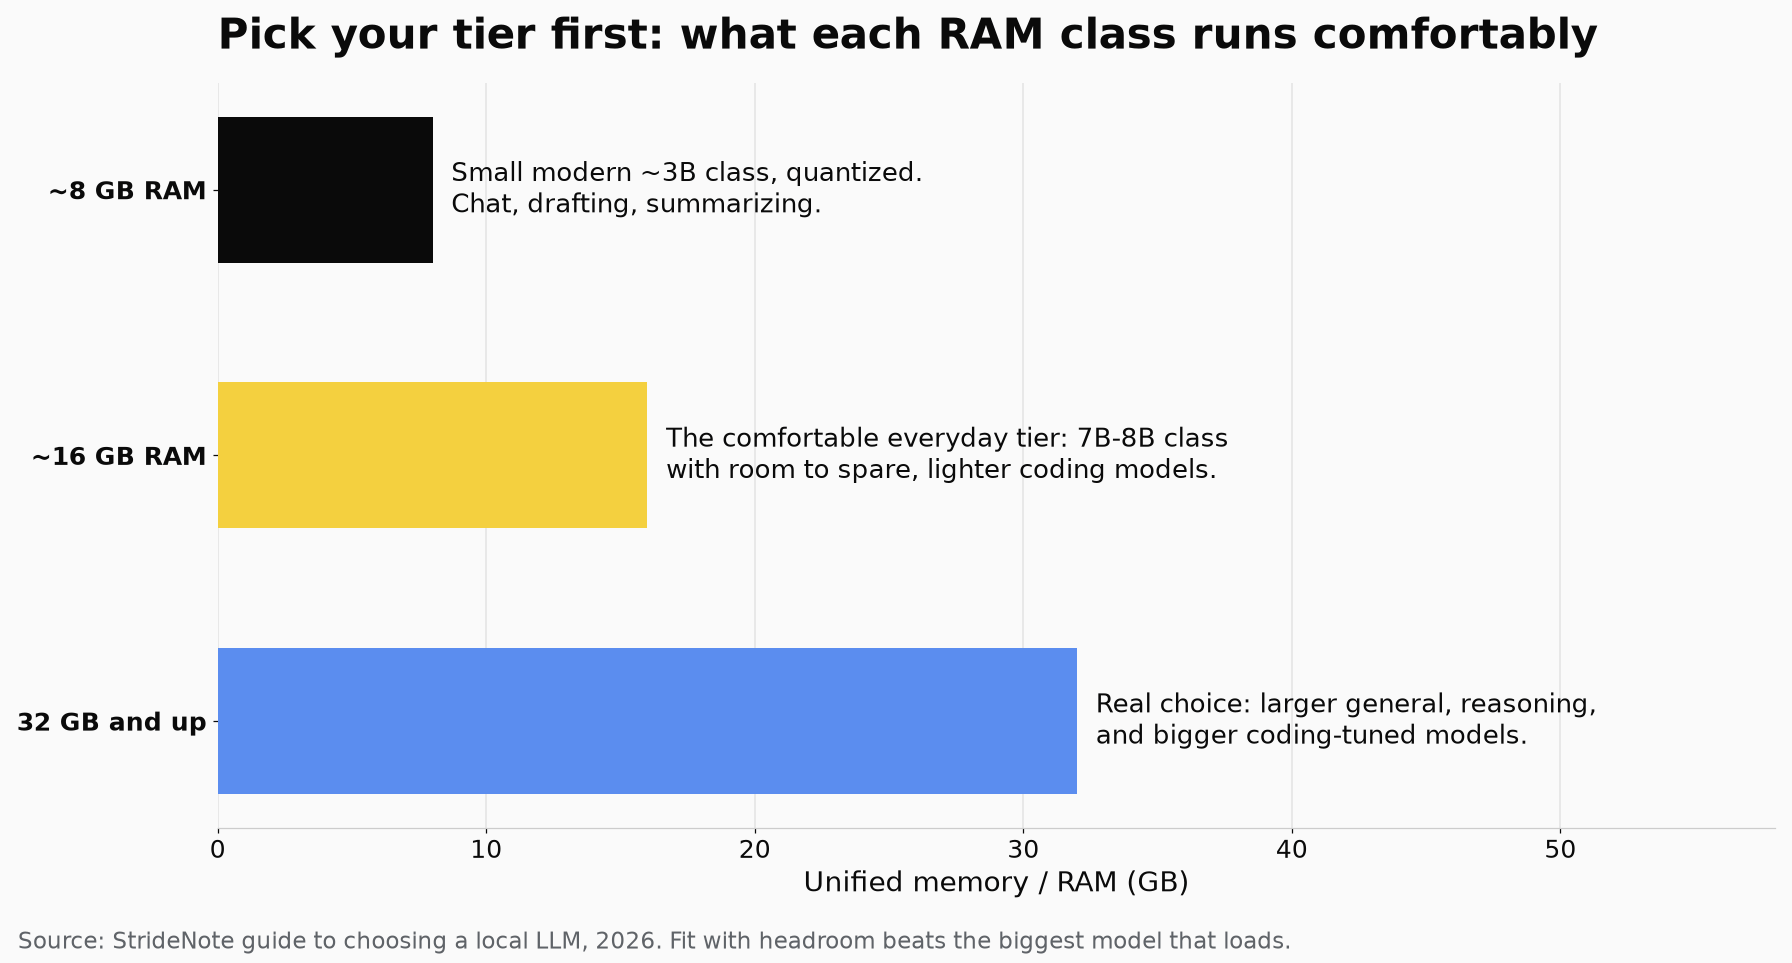
Pick the tier that fits your RAM with headroom first, then choose the model for the job inside it.
Which local LLM fits your RAM?
Around 8GB, you are in small-model territory, and that is fine for real work. Run a small, modern general model in the 3B-ish class, quantised. It will handle chat, drafting, summarising, and simple questions over text comfortably. Do not try to load a large model here; it will not end well. The smallest tier is not a consolation prize, it is the correct choice for this machine.
Around 16GB is the comfortable everyday tier, and the recommended floor for a reason. You can run capable mid-size general models, a 7B-to-8B class model with room to spare, and lighter coding-tuned models. Most people doing ordinary work should aim here. It is enough for a good chat model and a usable coding assistant without fighting your memory.
At 32GB and up, you have real choice. Larger general models, stronger reasoning models, and bigger coding-tuned models all become practical, and on Apple Silicon the unified memory is shared with the GPU, so more RAM directly buys you bigger models. If you are on a Mac with serious memory and you run long jobs, the MLX note in the Atlas points out it runs models 30 to 50 percent faster than equivalent PyTorch code on the same machine, which is worth claiming when you are letting a model grind.
Pick your tier first. Then, inside it, pick for the job.
Which local LLM for chat, coding, or reasoning?
For everyday chat, drafting and summarising, reach for a current general-purpose instruct model from a mainstream family. Llama and Mistral models are the dependable defaults here, well-supported and forgiving. Pick the largest one that fits your tier comfortably and stop optimising. For this work, “good enough” is genuinely enough, and the difference between a solid mid-size model and the absolute best is something you will rarely feel.
For coding and agent work, use a coding-tuned model rather than a general one. The Qwen coding-tuned line and other purpose-built code models are the families to look at, and a coding model that behaves well inside an agent loop matters more than one that merely writes a clean function in isolation. Match the size to your RAM, and remember that for an agent, staying in the tool-use loop reliably can matter more than peak code quality on any single step.
For reasoning and harder problems, bigger models and reasoning-tuned models earn their memory. If you have the RAM, a larger or reasoning-focused model will think through multi-step problems more reliably. If you do not have the RAM, this is also the category where you are most likely to still want a cloud model for the genuinely hard cases, and that is an honest trade rather than a failure.
For a business, decide job by job, not tool by tool. Drafting, rewriting, transcription, questions against your own files and routine coding are the jobs a local model handled every day on our test machine. Dense reasoning on a rare hard problem is the one job we still send to a single cloud tool.
What is the best local LLM in 2026 for support replies, summaries and coding?
Each business task leans on a different part of a model’s speed, and we have measured both parts on our test machine, an M4 Pro with 48 GB of unified memory. We have not scored any model’s answers on real support replies, document summaries or an agent coding task, so the table pairs each task with what it waits on and our measured speed, not with a quality verdict. That scoring, and the same speeds on 16 GB and 32 GB machines, is on our list.
| Business task | What it waits on | Our measurement | What it means for one request |
|---|---|---|---|
| Support replies | Generation speed, for a short answer | Gemma 4 31B: 11.0 tokens a second. Qwen3.6 35B-A3B: 49.4 on llama.cpp, 61.5 on MLX | A 300-token reply takes about 27 seconds on Gemma 4 31B (300 / 11.0) and about 5 to 6 seconds on Qwen3.6 35B-A3B (300 / 61.5 = 4.9; 300 / 49.4 = 6.1) |
| Summaries of long documents | Prompt processing, for the document going in | Gemma 4 31B: about 65 tokens a second, uncached | A 5,197-token prompt waited 79.56 seconds before the first token of the answer |
| Coding with an agent | Both, plus the agent’s own system prompt | OpenCode’s system prompt: about 51,700 tokens | About 13 minutes before the first answer of a session on Gemma 4 31B (51,700 / 65), then cached |
Sources: local LLM benchmarks on the M4 Pro, LM Studio parallel requests on MLX, our Gemma 4 26B MoE piece for the prompt wait, and agent skills vs MCP servers for the OpenCode prompt. All measured on our 48 GB test machine.
Two practical points follow from the numbers. For support replies, where a customer is waiting, the mixture-of-experts model’s measured speed is the difference between an answer in seconds and one in half a minute, so try Qwen3.6 35B-A3B on your own replies and judge its answers before choosing. For summaries, the wait grows with the length of the document, so long documents are a job to queue rather than to sit through. These speeds are only ours. We have not measured a 16 GB or 32 GB machine, and the 31B and 35B-A3B models above were run on 48 GB. The smallest model we have timed, Qwen 3.5 9B at a median 32.3 tokens a second on our 48 GB machine, is the nearest size we have measured to the 7B-to-8B class this guide places at 16GB. Across the sizes we timed for our offline OpenCode guide, local models ran at between 9.6 and 32.3 tokens a second on this machine.
Those are one person’s numbers. We have not measured how many people one machine serves at once before replies slow to the point of being unworkable; that needs several staff on a fixed drafting task against the same machine, and it is on our list.
Why is the biggest model rarely the right one?
The instinct to run the largest model your machine will technically load is the wrong instinct. A model that fits with headroom, runs fast, and matches your task will serve you better every single day than a bigger model that makes the laptop stutter and that you only feel the benefit of on rare hard problems.
This is the whole philosophy in one line: right-size to your RAM, match to the job, and let “good enough” win. The biggest model is the right answer surprisingly rarely. The model that fits and fits the work is the right answer almost always.
Good enough is not the same as best. On the hardest problems, a frontier cloud model is still ahead. If your work lives at that frontier all day, keep the cloud tool that earns it. We keep exactly one, for the dense reasoning jobs that come up rarely. Local asks you to own the upkeep: the occasional model update, the disk space, the rare afternoon spent fixing your own setup. In return it removes the meter, the rate limit, the outage, and the policy you did not write. For a team that runs all day, that is a trade worth making for the ordinary work and worth declining for the rare hard problem.
Which local models do we run?
Ollama is the foundation we start from: one command pulls a model, and it serves that model locally so every other tool can reach it. On Apple Silicon we reach for MLX when a job runs long enough for its speed advantage to matter, such as batch transcription or an evaluation run. The model choice follows exactly the logic above: a capable general model for everyday work, a coding-tuned model for the agent, each sized to the machine it runs on rather than to a leaderboard.
For our coding agent we run glm-4.7-flash locally, not because it tops a coding chart but because it behaves well inside the agent loop and fits our machines with room to spare. OpenCode, the desktop app, reads our files, edits them and runs commands with that model, and it keeps working with the Wi-Fi off. We expected to keep a cloud agent for “real” work and use local for toys. Instead the local setup carried the daily load, and the cloud became the exception we open a few times a month instead of a few times an hour.
For writing we run gemma4:31b, through a local chat on top of Ollama that handles drafting, rewriting, quick reasoning and questions against our own files. The reasoning behind keeping both on our own machines is its own argument. Our two-model split assumes 48 GB, so pick per machine using the tiers above rather than copying it.
That is the pattern we would point you to: decide your tier, decide your job, pick the model that fits both with headroom, and only chase a bigger one when you can actually feel its absence. To test it as a business, pick the one job your team does most often, run it locally for a full normal week, and count how many times anyone opened the paid tool. That count, not our numbers, says whether the subscription can go. We made that move in stages and wrote down the order in our guide to leaving paid AI tools one at a time.
Start with your RAM, not with a model name. The rest follows.
Two comparisons go deeper than this shortlist. We set out how to choose a local coding model for OpenCode, with the vendor SWE-bench scores and our own speeds, and put Gemma 4 31B against Qwen 3.5 27B on unified memory.