The two icons sit side by side in the Applications folder now, and choosing between them has become the first decision anyone makes when they decide to run AI locally on a Mac. One is a polished desktop app that looks like it belongs in a creative studio. The other is a terminal command that pulls models the way Docker pulls containers. Both run the same models. Both keep your data on your machine. But in 2026, after years of rapid development, the gap between them is no longer about capability. It is about how you want to work. For a business, the sharper question is whether one person will use it or a whole team will share it, and on that we have our own measurements for LM Studio.
Ollama has surpassed 162,000 stars on GitHub, while LM Studio has pushed to version 0.4.16 with a new headless daemon called llmster and native MLX support. The two tools have never been closer in raw performance. They have also never been further apart in design philosophy. Two more names come up in the same decision: Apple’s MLX framework used directly, and Jan, a desktop chat app. We cover where they fit too.
What do Ollama and LM Studio actually do?
Ollama is a CLI wrapper around llama.cpp written in Go. It auto-downloads GGUF model files, manages a local model registry in ~/.ollama/, and exposes a REST API on port 11434 that is compatible with the OpenAI client specification. On a Mac, it compiles llama.cpp with the Metal backend by default, which gives GPU acceleration through Apple’s graphics framework. The entire setup is a single curl command piped to sh, and running a model is one line: ollama run llama3.3. We walk through the full process below.
LM Studio is a desktop application built on Electron that wraps both llama.cpp and Apple’s MLX framework. It provides a graphical interface for browsing Hugging Face, downloading models, adjusting parameters, and chatting. It also runs a local server on port 1234 that speaks the OpenAI API format. The 0.4.0 release in January 2026 added llmster, a headless daemon that separates the inference engine from the GUI, making LM Studio viable for server deployments and CI pipelines.
The shared foundation is llama.cpp. Both tools use it. But the critical difference on Mac is MLX. LM Studio has supported MLX models since early 2024. Ollama added an MLX backend in version 0.19, released as a preview in March 2026. The 32 GB memory requirement repeated in early coverage is not in its code, as our read of the MLX engine found.
How do you install Ollama on a Mac?
You need an Apple Silicon Mac (M1, M2, M3, M4 or newer), 16GB of RAM recommended (8GB runs small models but gets tight fast), and roughly 10GB of free disk to start. Models are large, and they add up.
There are two clean install options. Either download the macOS app from https://ollama.com/download and open it, which installs the background service and a small menu-bar presence, or, if you keep your tools in Homebrew:
brew install ollama
Both land in the same place. After install, Ollama runs as a background service, so there is usually nothing to launch. If you ever need to start it by hand, run ollama serve. Then pull a small first model to confirm everything works:
ollama run llama3.2
The model downloads on first run (about 2GB), then drops you into a chat. Press Ctrl+D to exit, and use ollama list to see what you have on disk. If the download stalls or the command is not found, the usual cause is that the background service has not started yet: run ollama serve in one terminal and the model command in another.
Then prove it is local. With a model pulled, turn off your Wi-Fi and run ollama run llama3.2 again. Ask it a question. It answers, and nothing left your laptop.
Ollama is also already serving. You can hit it directly:
curl http://localhost:11434/api/generate -d '{
  "model": "llama3.2",
  "prompt": "Write a haiku about the ocean.",
  "stream": false
}'
Because it is OpenAI-API compatible at http://localhost:11434/v1, you point other tools at that address and they treat your local model like any cloud model. Every local-AI tool you add afterward reuses that one endpoint instead of bundling its own model.
Which Ollama settings matter after install?
- Models live in
~/.ollama/models/. This folder grows quietly into tens of gigabytes. Remove models you no longer use withollama rm <model>. - Memory is sticky. Once a model loads, it stays in RAM until something bumps it. Run
ollama psto see what is currently loaded. If your Mac feels slow, this is usually why. - Right-size the model to your RAM. A 7B model is comfortable on 16GB. Larger models want 32GB or more. Pulling a 70B model on a 16GB Mac will technically download and then crawl.
A practical starter set for a 16GB Mac is a small general model for quick chat and drafting, one coding model (for example qwen2.5-coder:7b) if you write code, and one slightly larger general model for when quality matters more than speed. Browse the full library at https://ollama.com/library and pull tags by name with ollama pull <model>.
How does the MLX performance gap work on Mac?
MLX is Apple’s open-source machine learning framework, released in late 2023. It routes matrix operations directly to Metal and the Neural Engine, and it uses unified memory without double-buffering. The practical result is that MLX runs models faster and uses less memory than the llama.cpp Metal backend on the same hardware.
Ollama’s own testing puts numbers on that gap. On Qwen3.5-35B-A3B, Ollama 0.19 on MLX decoded at 112 tokens per second against 58 for Ollama 0.18 on its llama.cpp path, and prefilled at 1,810 tokens per second against 1,154. The catch is memory in practice, not a gate: the MLX models that gain most are the large ones, so a small Mac sees less of the benefit.
When is MLX used directly still worth it?
Paired with the mlx-lm package, MLX is the most direct way to run a model on a Mac. It is Python-first and Mac-only, so using it well means a little code and comfort with venvs and pip, and sometimes converting a model into the MLX format if it is not already on the mlx-community hub.
Now that Ollama runs on MLX, the old story of a large and simple gap between direct MLX and Ollama has mostly closed for everyday use. Direct MLX still wins at the edges: the newest optimizations land there first, and long batch jobs, evaluation runs and fine-tuning pipelines benefit from its raw throughput and Python control. For a one-off chat you will not feel any of it. The cleaner way to think about it is Ollama for running, MLX for building. If you want to fine-tune a model on your own data, convert weights, or sit closest to Apple’s latest kernels, drop down to MLX directly and accept the Python setup.
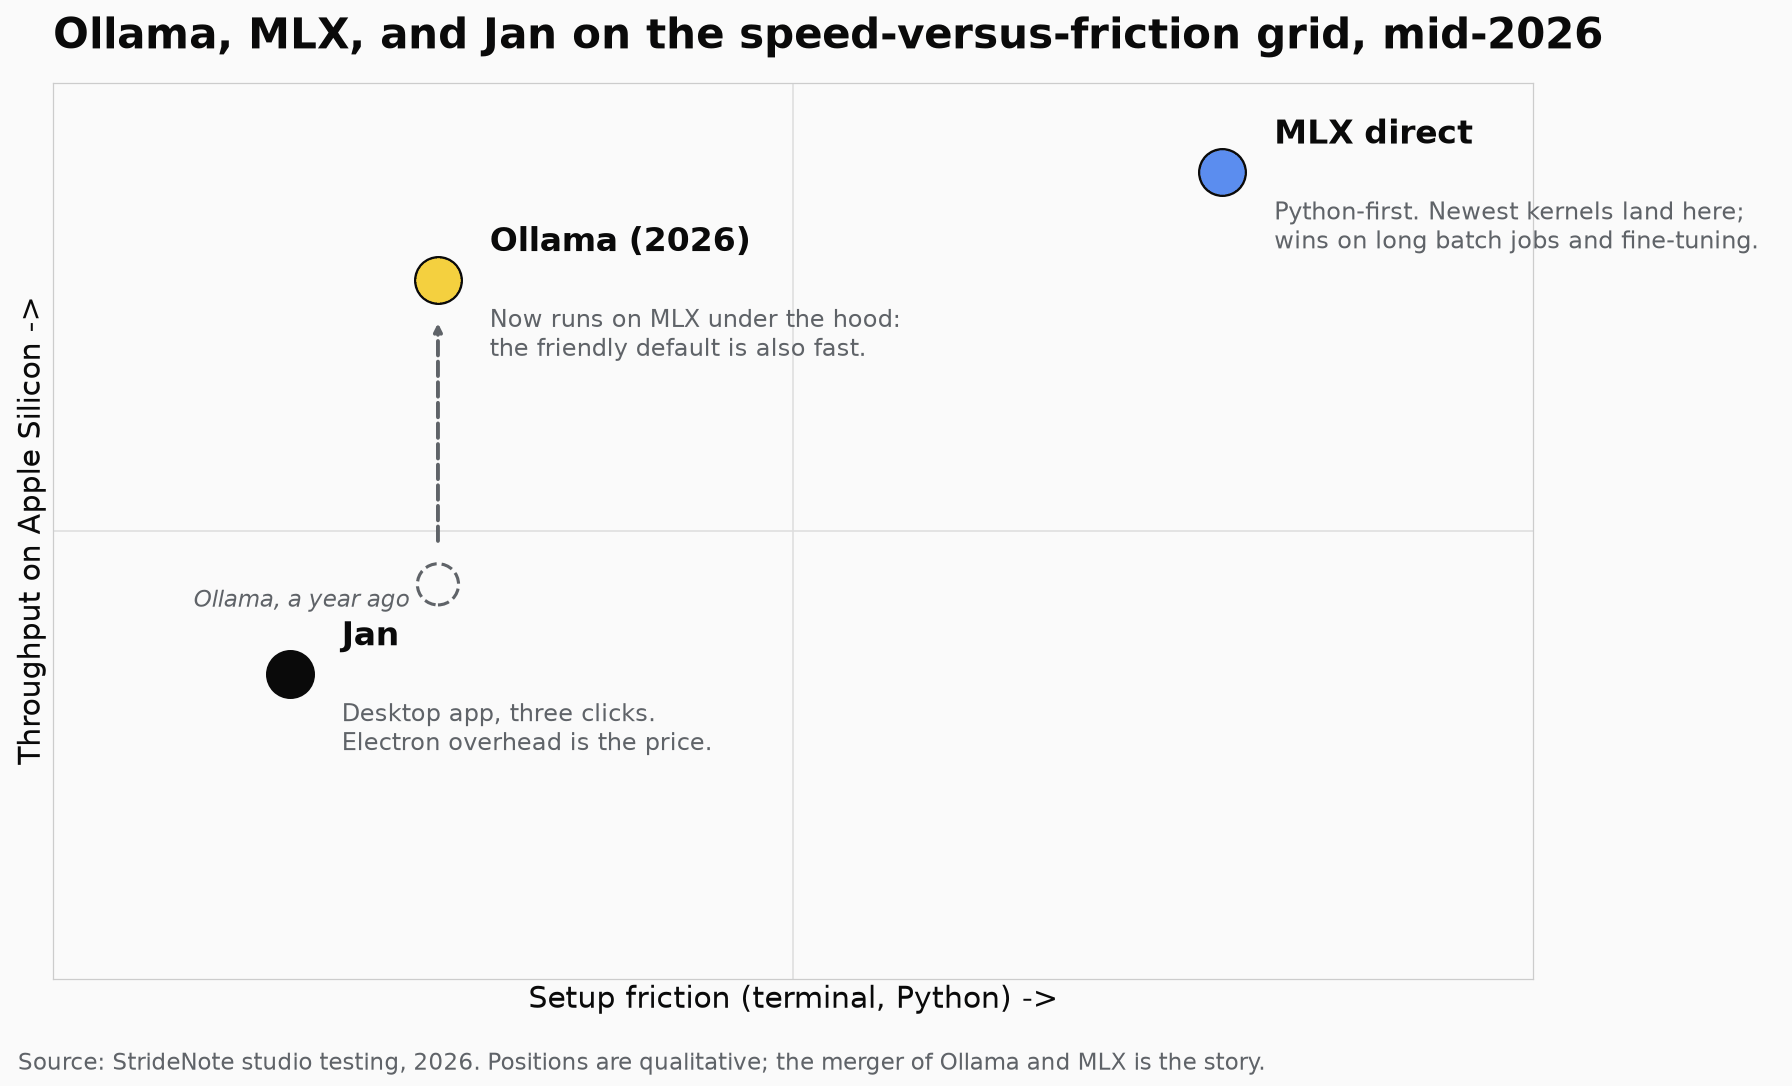
Where each tool lands on speed versus setup friction. Jan is the easiest and carries the most overhead; direct MLX is the fastest and the most setup.
Which tool fits your workflow better?
The choice comes down to whether you live in the terminal or in a window.
Ollama is built for people who think of AI models as services. You pull a model, you run it, you point something at its API. The CLI is fast and minimal. The REST endpoint supports chat completions, embeddings, streaming, and function calling. Tools like Continue.dev, Cursor, Aider, and Open WebUI connect to it natively. Docker deployment is a single command with the official image. If your workflow involves scripting, automation, or integrating models into applications, Ollama is the natural choice.
LM Studio is built for people who want to explore models before committing to a workflow. The built-in model browser shows VRAM requirements before you download anything. The chat interface lets you compare models side by side with split view. Parameter sliders for temperature, top-p, and max tokens are right there without needing a Modelfile. The 0.4.x releases added chat export to PDF and markdown, a developer mode with advanced options, and a local server that supports both OpenAI and Anthropic API formats.
The line between them has blurred since January 2026. LM Studio’s llmster daemon gives it a headless mode that can run on servers without a display. Ollama added a native GUI in its 2026 Windows release and a launch command for connecting to tools like Codex and OpenCode. But the default experience of each tool remains different. Ollama’s first interaction is a terminal prompt. LM Studio’s is a search bar and a download button.
Where does Jan fit?
Jan is a desktop chat app that bundles its own runtime. Download it, pick a model from its Hub, and chat. No terminal, no Python, no Docker. It is three clicks to a working model, and the tool we hand to someone who would otherwise never try local AI, because the barrier was never the model, it was the terminal. It is Electron, so a few hundred megabytes of RAM go to the UI before the model loads, and on a 16GB Mac running a 7B model it gets tight. Of Jan, Ollama and direct MLX, Jan carries the most overhead, which is the cost of being the friendliest.
One detail bites people. Jan’s bundled runtime keeps its own model store, separate from Ollama’s. A model you download in Jan does not appear in Ollama, and vice versa, unless you configure Jan to use Ollama as a remote backend. If disk space matters, do not download the same 4GB model twice: either centralize on Ollama and point Jan at it, or accept two stores on purpose. If a chat UI is all you want, the Open WebUI versus Jan question is the next one to settle.
What do the ecosystem and integrations reveal?
Ollama’s ecosystem advantage is structural. Because it is MIT-licensed and CLI-first, every tool that supports local models treats Ollama as the default backend. Open WebUI gives it a ChatGPT-grade web interface. Continue.dev and Twinny provide VS Code autocompletion. LangChain and LlamaIndex connect to it for RAG pipelines. The ollama launch command wires models directly into coding tools like Codex and OpenCode with a single command.
LM Studio’s ecosystem is smaller but more focused on desktop workflows. Its local server supports the same OpenAI-compatible API, so many of the same tools work with a URL swap from localhost:11434 to localhost:1234. The lms CLI, introduced with 0.4.0, provides terminal access for downloading models, starting the server, and running interactive chat. But the community has not rallied around LM Studio the way it has around Ollama. Open WebUI, for instance, does not target LM Studio as a primary backend.
The model format situation adds another dimension. LM Studio supports both GGUF and MLX formats natively. Ollama uses GGUF exclusively, though its MLX backend in 0.19+ can serve models stored in MLX format. For Mac users, LM Studio’s dual-format support is a practical advantage because MLX models are widely available on Hugging Face through the mlx-community organization, and they run better on Apple Silicon, as set out in the section on direct MLX.
Which one should you pick based on your Mac in 2026?
The answer depends on your hardware tier and your tolerance for the terminal.
If you have the memory for the larger MLX models, Ollama 0.19 or later runs on MLX, and you get that engine with Ollama’s superior ecosystem. This is the best combination in 2026: fast inference, every tool integration, and Docker support when you need it.
If you are on a Mac with 16 GB or 24 GB, you cannot use Ollama’s MLX backend, but LM Studio still runs native MLX models. For these machines, LM Studio is the better choice if performance matters.
If you are on an Intel Mac, MLX is unavailable entirely. Both tools fall back to llama.cpp with Metal or CPU. Ollama is the simpler option here because it avoids the Electron overhead of LM Studio’s GUI.
If you are a developer building applications, pick Ollama. The API is the point. The ecosystem is the point. The containerized deployment is the point. Even on a 16 GB Mac, the convenience advantage outweighs the raw throughput gap for most development use cases.
If you are a researcher, writer, or non-technical user who wants to experiment with local AI, pick LM Studio. The GUI removes every barrier to entry. The model browser tells you what fits before you download. The chat interface is good enough that you may never need another frontend. If the person will not open a terminal at all and only wants a private chat window, Jan is the other candidate.
Add direct MLX only if you have long jobs where the clock matters, or you want to fine-tune. And if you need to serve many users at once, that is a vLLM job rather than an Ollama or LM Studio one.
LM Studio vs Ollama for one person or a shared team server: which to pick?
We have timed LM Studio on our test machine, an M4 Pro with 48 GB of memory, with one caller and with two at once. We have not timed Ollama the same way. All figures are tokens written per second except the last row, from our test of LM Studio parallel requests and our MLX vs llama.cpp run on Qwen3.6 35B-A3B, both on 12 October 2026.
| Use | LM Studio, measured on our test machine |
|---|---|
| One person, Gemma 4 31B | 11.7 on the llama.cpp engine, 12.6 on the MLX engine |
| Shared server, two requests at once, Gemma 4 31B | 5.7 each on llama.cpp (11.4 combined), 11.5 each on MLX (23.0 combined) |
| Shared server, two requests at once, Qwen3.6 35B-A3B | 39.4 each on llama.cpp (78.8 combined), about 64.7 each on MLX (129.4 combined) |
| Long agent prompt, about 20,000 tokens, Qwen3.6 35B-A3B | 74.8 seconds to the first token on llama.cpp, 30.3 on MLX |
For one person, the speeds do not decide it, and the workflow sections above do. For a team sharing one Mac, the engine inside LM Studio mattered more than anything else we changed: on Gemma 4 31B the MLX engine doubled the combined output, where llama.cpp split the same output between two callers. LM Studio’s parallel requests page, read on 17 October 2026, sets Max Concurrent Predictions to 4 by default and still says MLX support is coming, although our run on MLX engine 1.11.0 already shared the model.
Ollama’s FAQ, read the same day, gives OLLAMA_NUM_PARALLEL a default of 1, so a second caller waits in a queue unless that setting is raised. We have not measured what raising it does on a Mac, and we have tested two callers on LM Studio, not three or four. The same one-caller and two-caller runs on Ollama with the same models, and three and four callers on LM Studio, would settle it, and both are on our list. On our two-caller evidence a small team that wants a shared server would start with LM Studio’s MLX engine, with one caution we recorded: the Qwen3.6 MLX build returned schema-bound JSON in the wrong field.
Every laptop or one shared machine?
The first shape is a runtime on every laptop. With Ollama, each person gets the endpoint at http://localhost:11434 and their prompts never cross the office network. The cost is per machine: 16GB of RAM recommended, roughly 10GB of free disk to start, and a models folder on each Mac that someone has to keep tidy.
The second shape is one larger Mac that holds the models for everyone. It saves disk on every laptop and puts one person in charge of model choice. It also changes the security picture. Ollama listens on localhost by default, so other machines cannot reach it until you deliberately open it to the network, and once you do, anyone on that network can send it work. If you take this route, decide who may reach it before you change anything.
For a first rollout, standardise the boring parts. Pick one install method (the app or Homebrew, not a mix), write down the model tags staff should pull, and put ollama ps and ollama rm in the support note so that held memory and a full disk can be cleared without a call.
Which tool should each member of staff get?
A business rarely needs one answer for everyone. Give Jan to staff who will never open a terminal and only want a private chat window: someone drafting client letters, a manager summarising notes. Budget for its Electron overhead on 16GB machines, and decide at setup whether Jan keeps its own model store or points at Ollama. Put Ollama on any machine where other tools need a model, such as a coding agent, an editor plugin or a documents app. Keep direct MLX for the one or two people who build things, such as an engineer who wants to fine-tune a model on your own documents or run long evaluation jobs. It belongs on their machines, not on the standard image.
What makes this comparison different from a year ago is that both tools are now visible in the same conversation. Ollama has grown past being just a developer command-line tool. LM Studio has moved beyond being a pretty GUI with slower inference. The MLX backend in Ollama 0.19 and the headless daemon in LM Studio 0.4.0 have each crossed into the other’s territory. The question in 2026 comes down to a simpler metric: which tool matches the way you already work.
With a runtime installed, the next steps all reuse one endpoint: a local AI coding agent on a Mac, AI autocomplete in your editor, or a tool that lets you ask questions of your own documents. For which model to pull and whether the newer 4-bit format is worth the disk, we cover running Gemma 4 12B locally and what NVFP4 changes for local model quality. The wider local AI stack plugs into the same place.
One LM Studio behaviour that only shows up on reasoning models is worth knowing before you choose: a large input can come back as an empty reply with an HTTP 200. What an LM Studio empty response means, and the fix.