A Mac with 24 GB of unified memory loads a 19 GB model into the same pool the GPU reads from. No copying. No VRAM ceiling. Just a single allocation that determines whether inference runs at a steady pace or slows to a crawl. That is the promise and the constraint of Apple Silicon for local LLMs, and it is the frame for the most contested open-weight matchup of 2026: Google DeepMind’s Gemma 4 31B versus Alibaba’s Qwen 3.5 27B. For a business choosing a model to put behind staff tools or agents, our newer measured runs, summarised below, matter more than the benchmark sheets.
Both models are dense, both sit just under 30 billion parameters, and both fit on a single consumer-tier Mac with enough quantization. But they make radically different trade-offs on unified memory. Gemma 4 31B scores higher on reasoning benchmarks and ranks third among open models on the LMArena leaderboard at 1452 ELO. Qwen 3.5 27B leads on multilingual coverage, and its thinking mode adds a capability Gemma 4 does not natively match. The choice between them is not a winner-take-all verdict. It depends on your memory tier, your context window needs, and how much thinking you actually want the model to do.
What does unified memory mean for 27B and 31B models?
Apple Silicon’s unified memory architecture is the reason a Mac can run models that would exceed the VRAM of many discrete GPUs. On an M-series chip, the 19 GB Gemma 4 31B Q4_K_M GGUF loads into the same memory pool the GPU uses. There is no PCIe transfer and no artificial VRAM boundary. The catch is that all of the model must fit alongside the operating system, the KV cache for your context window, and whatever else is running.
The math is straightforward. The model at Q4_K_M takes 17 to 20 GB depending on the format. The context window is charged on top of that. On our own 48 GB M4 Pro, the Gemma 4 31B QAT process held 21.97 GB at an 8,192-token context and 23.84 GB at 32,768 tokens, against an 18.85 GB file, as measured in our context window test. When weights plus context outgrow the memory left after the operating system, the system swaps to SSD, and throughput drops from usable to frustrating. This is the core tradeoff behind our guide on how to pick a local model for your RAM.
The solution for each memory tier is different. On a 24 GB Mac, Gemma 4 31B barely fits with a reduced context window. On our 48 GB M4 Pro it runs at a 64K context and generates at a median 11.0 tokens per second, as recorded in our test of LM Studio’s default context length. The same principle applies to Qwen 3.5 27B, which takes roughly 17 GB at 4-bit and leaves more headroom for context, but the KV cache cost is lower because Qwen uses DeltaNet linear attention layers that compress the memory footprint.
How does Gemma 4 31B perform on benchmarks?
The case for Gemma 4 31B is the benchmark sheet. On AIME 2026, the model scores 89.2 percent. On LiveCodeBench v6, it scores 80.0 percent. On GPQA Diamond, it scores 84.3 percent. The jump from Gemma 3 27B is not incremental. The previous generation scored 20.8 percent on AIME and 29.1 percent on LiveCodeBench.
What matters more for local deployment is token efficiency. On a memory-bandwidth-bound Mac where every generated token costs time, the length of a model’s reasoning trace compounds across a session.
Google recommends a temperature of 1.0 and a top-k of 64 in the Gemma 4 31B model card, settings that normally increase output variability.
How does Qwen 3.5 27B perform on benchmarks?
On the benchmarks the two model cards share, Qwen 3.5 27B and Gemma 4 31B are close. Qwen’s model card puts it at 80.7 percent on LiveCodeBench v6, against Gemma 4’s 80.0 percent. It gives no AIME score to set against Gemma 4’s 89.2 percent on AIME 2026, so the math comparison cannot be made from the cards.
Qwen 3.5 27B also leads on MMLU-Pro and GPQA Diamond. It achieves 86.1 percent on MMLU-Pro against Gemma 4’s 85.2 percent, and 85.5 percent on GPQA Diamond against Gemma 4’s 84.3 percent. The margins are small. Qwen also supports 201 languages against Gemma 4’s 140, and its 262K native context window is slightly larger than Gemma 4’s 256K.
On paper, Qwen’s smaller parameter count and linear attention architecture reduce memory bandwidth pressure during decode, which should favor it on speed. Our own measurement, in the next section, did not bear that out.
The smallest member of the family is tested in Gemma 4 E4B on edge hardware.
Which model runs faster on Apple Silicon?
The speed question on unified memory is a bandwidth question. Every token generated requires reading the model weights from memory. A 31B dense model reads 31 billion parameters per token. A 27B dense model reads 27 billion. The difference at Q4 is about 2 GB less data per forward pass.
On our 48 GB M4 Pro, in LM Studio with twelve runs each, Gemma 4 31B generated at a median 11.0 tokens per second and Qwen 3.5 27B at 9.6, as recorded in our test of LM Studio’s default context length. The Gemma build was a QAT file at Q4_0 and the Qwen build was Q4_K_M, which may account for part of the gap. We have not measured either model on an M4 Max.
The counterintuitive finding is that MoE models in both families outperform their dense siblings on unified memory. The Gemma 4 26B-A4B activates only 3.8 billion parameters per token but loads the full 26 billion into memory. It scores 1441 on LMArena. The Qwen 3.5 35B-A3B follows the same pattern. The memory cost is the full model size, but the decode speed matches a much smaller dense model.
What the 26B MoE needs at each memory tier, and how Google’s own card scores it against the 31B dense, is in Gemma 4 26B MoE on unified memory: 82.6% against 85.2% on MMLU Pro, and within three points on every row.
What is the hidden memory cost of thinking mode?
Qwen 3.5’s configurable thinking mode is its most distinctive feature. It allows the model to produce chain-of-thought reasoning tokens before the final answer, which improves performance on complex tasks. The cost is that those reasoning tokens share the generation budget and consume KV cache memory.
We have not measured Qwen 3.5 27B’s thinking traces on our own machine. The effect is visible on Gemma 4 31B, which also reasons before answering: in our prompt processing benchmark it produced 254 to 297 thinking tokens against 35 to 36 visible ones, and at the shortest prompt it spent its whole 297-token budget thinking and returned no answer.
The implication for unified memory is direct. Thinking mode multiplies the number of tokens generated per query. Each token requires reading the KV cache alongside the model weights. On a memory-bandwidth-bound Mac, the throughput drops in proportion to the thinking trace length.
Is the newer Qwen3.6 35B-A3B better than Gemma 4 31B for a business team?
Since this comparison was written, the Qwen line has moved on. On 11 September we measured Gemma 4 31B against the newer Qwen3.6 35B-A3B and Qwen3.8 27B on the same 48 GB M4 Pro. From here, Qwen3.6 means Qwen3.6 35B-A3B and Qwen3.8 means Qwen3.8 27B. The test, a board puzzle where the model must commit to one move, gave a result a business can act on: Gemma 4 31B answered in 11 of 12 runs at a median 10.9 tokens a second, Qwen3.6 in 4 of 12 at 50.8, and the dense Qwen3.8 in none of 12 at 8.7.
Why does Hermes recommend Qwen3.6 35B-A3B on a 48 GB Mac?
The test started with a badge. Hermes Agent put a blue “Recommended” badge next to Qwen3.6 the first time we opened its new Local Models page on our test machine. One click on “Set up for me” would have downloaded 21.9 GB, installed a llama.cpp engine and made the model our default for new chats.
The badge is a speed prediction, not a quality ranking. Hermes ships a catalog of four local models, and its own quality scores rate Qwen3.8 above Qwen3.6. The rule in Hermes’s catalog.py then drops any model it predicts will generate fewer than 20 tokens a second, a figure the code calls the pleasant floor. The prediction is memory bandwidth divided by the bytes read for each token, and machines with unified memory are assumed to move 210 GB a second. The comment beside that number says it was measured on unified-memory NVIDIA hardware, not on a Mac.
Qwen3.8 is a dense model, so every token reads all 16.5 GB of its weights, and Hermes’s formula gives it about 13 tokens a second. That is below the floor, so it is out. Qwen3.6 is a mixture of experts. Its model card lists 35 billion parameters with 3 billion active per token, and Hermes’s catalog prices it at 15% of the file per token, which the same formula turns into about 62 tokens a second. So the model Hermes rates lower is the one it recommends. Our measurements agree with the direction of that prediction, and Qwen3.8 came out slower than Gemma even with multi-token prediction switched on.
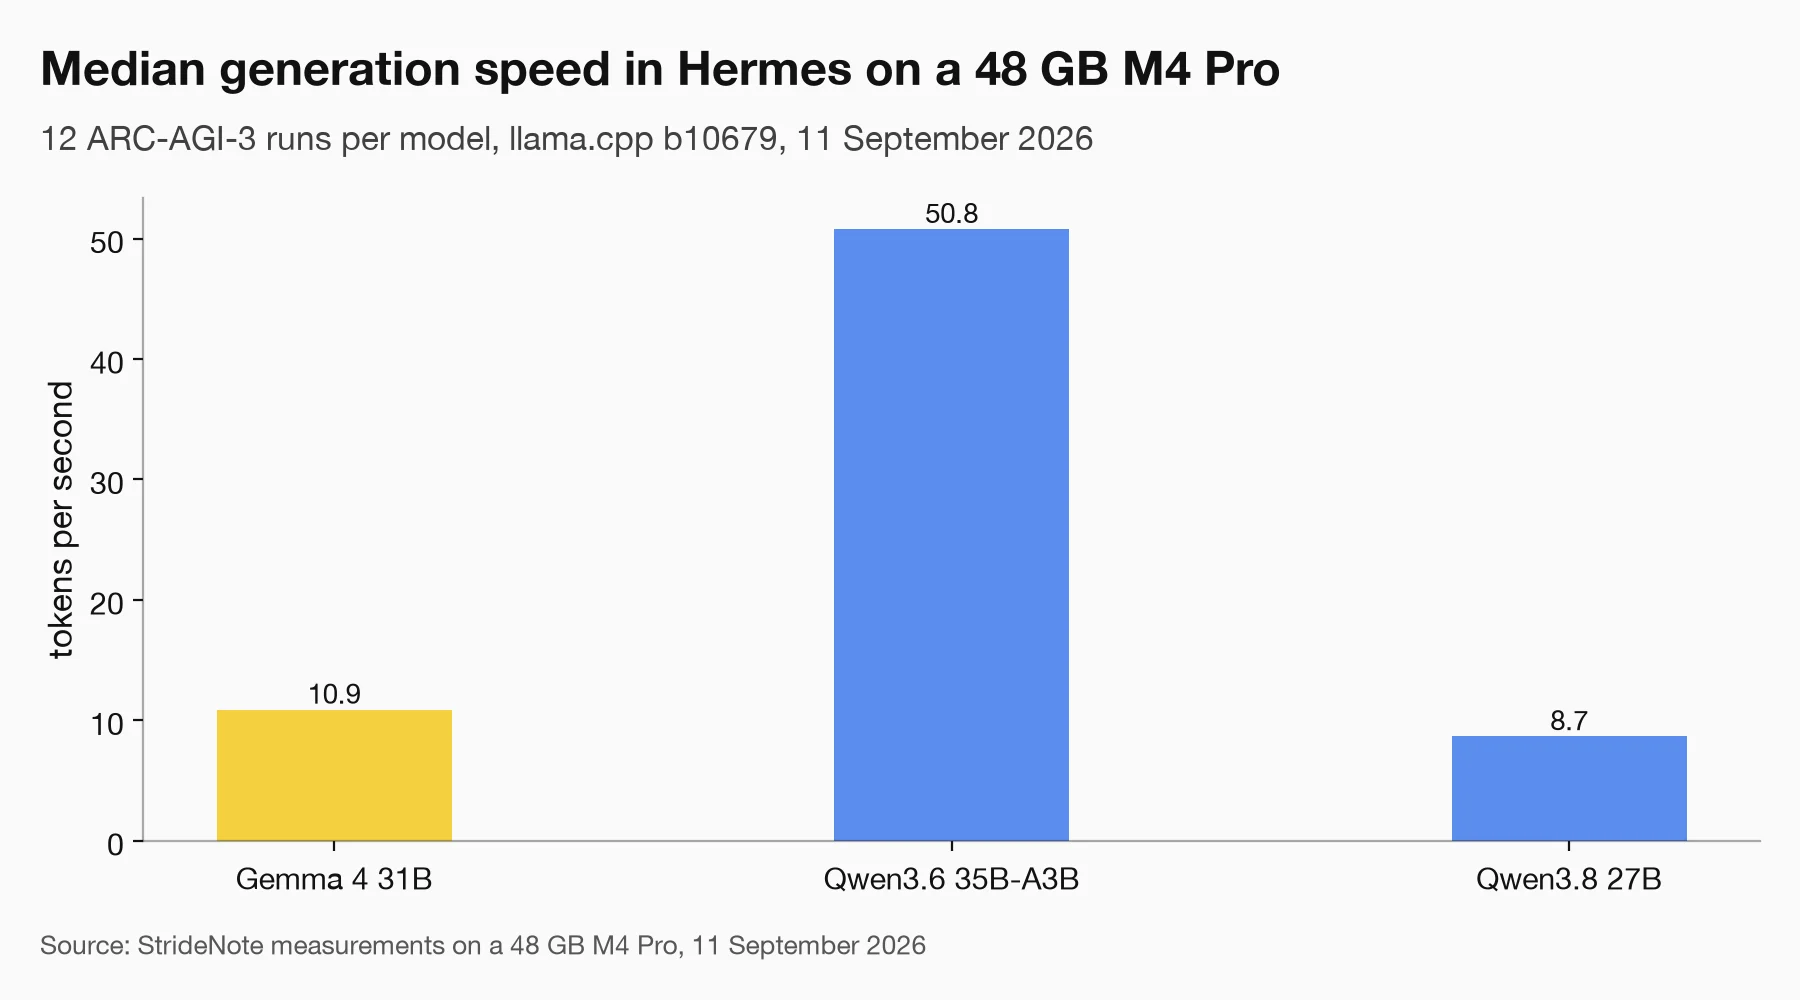
Median generation speed over 12 ARC-AGI-3 runs per model, Hermes’s llama.cpp build b10679, 11 September 2026.
How we tested Qwen3.6, Qwen3.8 and Gemma 4 in Hermes
Hermes desktop v0.21.1, the release that made Bot Mode the default, keeps local models under Settings, Providers, Local Models. The Download buttons do nothing until the engine is installed. Install runtime fetched llama.cpp build b10679 from GitHub, which took 37 MB on disk against the few hundred MB the page describes. Qwen3.8 then arrived in about four and a half minutes, 16.46 GB plus a 0.93 GB vision projector, and Qwen3.6 took about six minutes for 22.66 GB plus 0.90 GB. Both land in ~/.hermes/models, a folder LM Studio does not scan. We used “Configure” rather than “Set up for me”, so our default model never changed.
The test is the one from our guide to running ARC-AGI-3 on a Mac, the same board test behind our reasoning token counts. We took the first frame of the game ls20, reduced it to 8×8, 16×16, 32×32 and 64×64 grids of hex digits, listed the four legal actions and asked for one action name. Each model got three runs per board at temperature 0.2, with a cap of 16,384 output tokens and a 65,536 token context. Every run went through the llama.cpp server Hermes installs, with the launch settings Hermes’s own code writes: an 8-bit KV cache, flash attention and, for both Qwen models, multi-token prediction. The one change we made was the context, which we pinned to 65,536 for all three models so they match.
Gemma needed one more step. The memory estimator in Hermes’s estimator.py knows the attention layout of Gemma 2 and Gemma 3 but not Gemma 4. It prices Gemma 4 31B at about 72 GiB for a 64K context, so the code that writes launch settings declined it. The same engine loaded the same file at 65,536 context in 11 seconds once we gave it the settings Hermes uses for other dense models.
Two limits apply. A background job that keeps Gemma loaded in LM Studio for our assistant reloaded it at some point during the runs: when the Qwen3.8 sweep ended, an idle 18.85 GB copy sat in memory beside the test model. That does not change what a model writes, but the timings are not from a clean machine. The test also records whether a model commits to a move within budget, not whether the move is correct.
Answers, tokens and speed on the ARC-AGI-3 board
| Model | Runs with a move | Runs that hit 16,384 | Median speed | Median time per run |
|---|---|---|---|---|
| Gemma 4 31B | 11 of 12 | 1 | 10.9 tok/s | 2.7 min |
| Qwen3.6 35B-A3B | 4 of 12 | 8 | 50.8 tok/s | 5.2 min |
| Qwen3.8 27B | 0 of 12 | 10 | 8.7 tok/s | 31.5 min |
Gemma’s answers took between 666 and 3,413 tokens. Its one failure was a 64×64 run that spent the full 16,384 over 29 minutes. Qwen3.6 answered once on each board size, after 10,249, 12,756, 4,507 and 8,941 tokens. At its speed a failed run costs about five minutes rather than half an hour, but eight of its twelve runs ended the same way: 16,384 tokens and no move.
Qwen3.8 never gave a move. Ten runs hit the cap at about 30 minutes each, and two 64×64 runs stopped on their own after 3,377 and 13,616 tokens with an empty reply, the pattern we traced in LM Studio empty responses where reasoning eats the answer. The full sweep took 5.7 hours against 1.1 for Gemma and 0.9 for Qwen3.6.
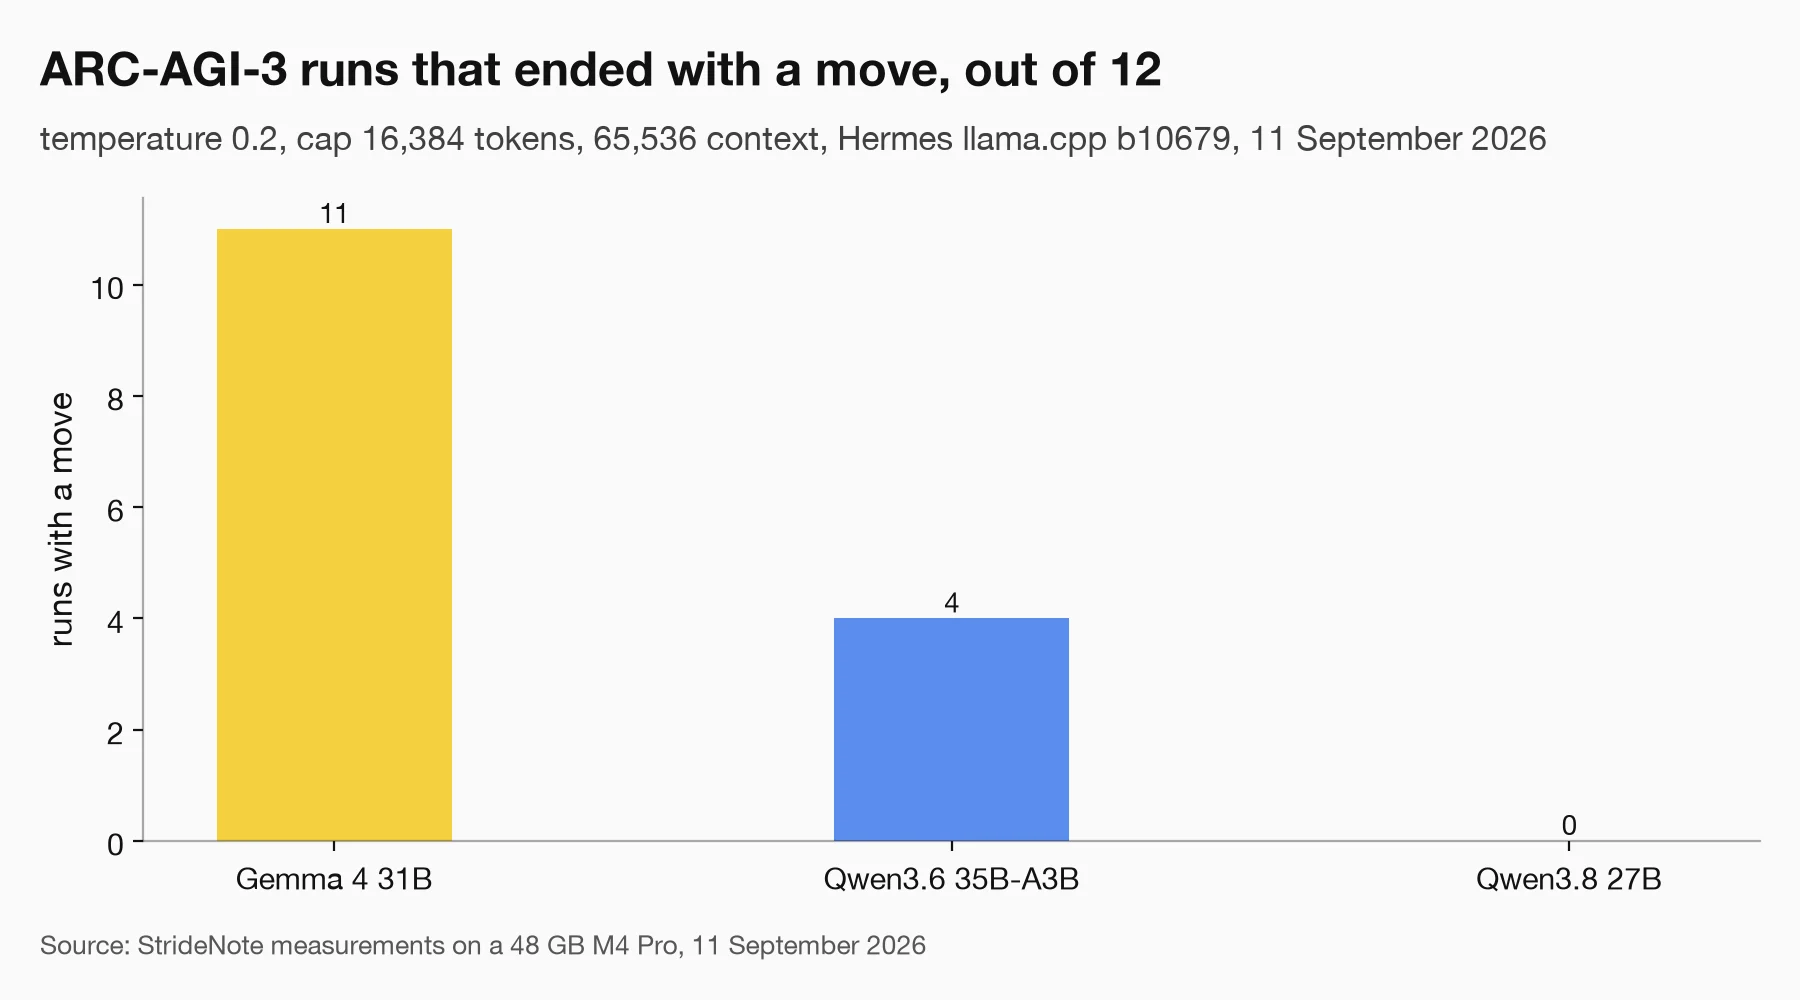
Runs that ended with a move, out of 12 per model, temperature 0.2 and a 16,384 token cap, 11 September 2026.
The models also read the board differently, and Gemma’s steadiness matches what the two Gemma 4 31B ARC-AGI-3 entries built their agents on. Gemma chose ACTION1 seven times and ACTION2 four times, including all three 32×32 runs. Qwen3.6 chose ACTION1 three times and ACTION3 once.
This matches the first time we measured the family. On 9 September the dense Qwen 3.6 27B ran the same boards in LM Studio, and all six of its runs stopped at 16,384 tokens with no answer. With the cap raised to 49,152 it answered the 8×8 board after 30,837 reasoning tokens and 47.7 minutes, where Gemma had needed 684 tokens and about a minute. How the cap interacts with a reasoning model is the subject of our piece on max_tokens for reasoning models.
Why Qwen3.6 runs out of tokens
Token counts cannot tell careful thinking from a loop, so we reran Qwen3.6 on the 8×8 board and kept the full reasoning text. One run answered ACTION2 after 8,245 tokens and 166 seconds. Its reasoning follows one idea, that an isolated cell is the player, all the way to a move. The other run hit the cap. For each quarter of each text we measured the share of 60-character stretches that had already appeared earlier in the same text.
The answered run repeated 0%, 2.0%, 5.7% and 21.8% of itself, quarter by quarter. The capped run started the same way, at 0% and 1.8%, then rose to 26.3% and 99.5%. By its last quarter almost every stretch was a repeat, and the phrase “Maybe the actions are” had restarted 38 times against 3 in the answered run. The server’s multi-token prediction counters point the same way. On one capped Qwen3.6 run, 96.8% of drafted tokens were accepted, and text that repeats itself is easy to predict.
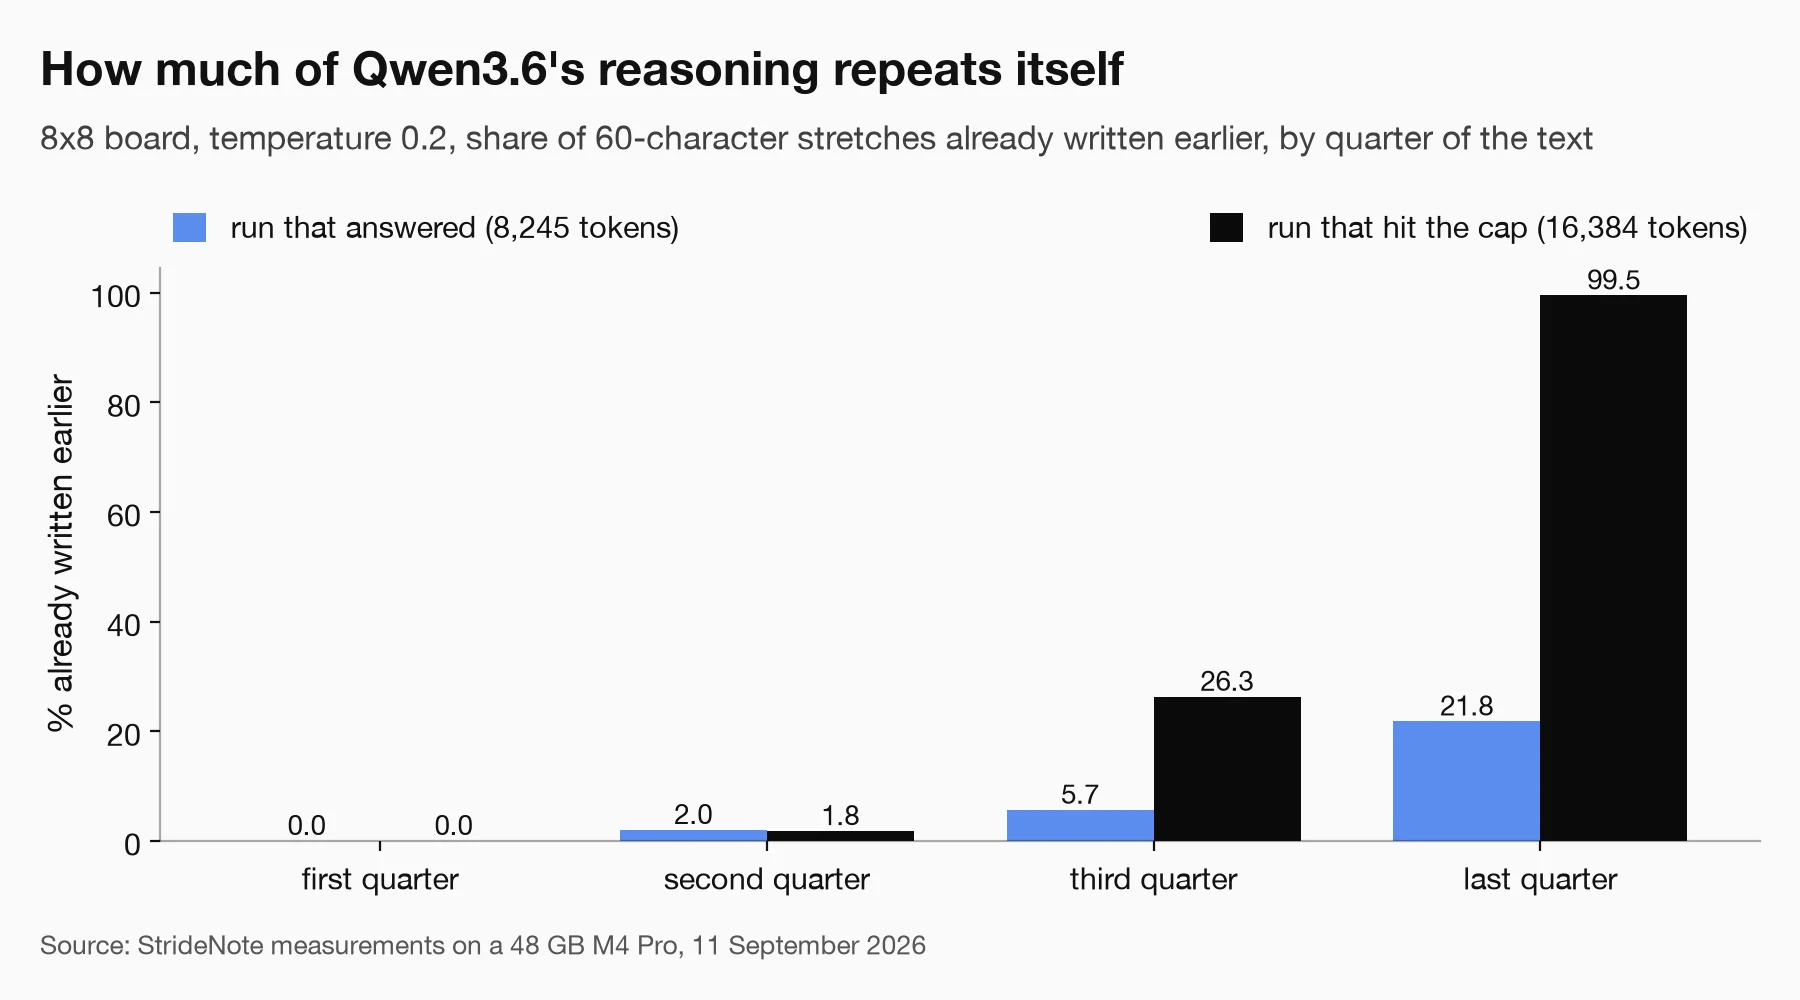
Share of 60-character stretches already written earlier, by quarter of the reasoning text, two Qwen3.6 runs on the 8×8 board at temperature 0.2, 11 September 2026.
Sampling is the open question. Qwen’s model card recommends temperature 1.0, top_p 0.95, top_k 20, min_p 0 and presence_penalty 1.5 for thinking on general tasks, and says a presence_penalty between 0 and 2 can “reduce endless repetitions”. Our test ran at temperature 0.2 with no presence penalty, the setting used across the whole series. On a 16×16 board, our LM Studio temperature tests found temperature made little difference to how much Gemma reasoned. Hermes’s own preset for Qwen3.6 sets temperature 1.0, top_k 20, top_p 0.95 and min_p 0 but no presence penalty. We have not measured either Hermes’s preset or the model card’s settings on this board. One looping run at 0.2 is an example of the failure, not a rate. The number still missing is Qwen3.6 with presence_penalty at 1.5.
Which should a team deploy now?
We would not choose between Gemma 4 31B and Qwen 3.5 27B on the benchmark cards alone. For a team the deciding question is what the model is for. Work that has to finish, such as an agent step that must return a usable answer, favoured Gemma in every run we made, and it is still the model we run for reading a grid and committing to a move, as it was when we set it against Bonsai 27B on a Mac. Work where speed per token matters more, such as a draft someone will edit anyway, is where Qwen3.6 earns a look, with the caveat that its runs that looped cost time. Qwen3.8, at 8.7 tokens a second and no answers in 12, is not a model we would put behind an agent on a 48 GB machine.
A few practical points follow. On a 48 GB Mac, plan for one model generating at a time: when we ran two models at once on 48 GB, both slowed sharply. Measure on your own task before rolling out; the Gemma and Qwen3.6 sweeps took 1.1 and 0.9 hours of machine time, a small cost against choosing the wrong model for a whole team. If Hermes already talks to Gemma through LM Studio, as in our always-on assistant setup with Hermes Agent and LM Studio, open “Configure” rather than “Set up for me”, because the one-click path changes the default model for new chats. The two Qwen downloads also stay in ~/.hermes/models after testing, 41 GB with their vision projectors, and LM Studio cannot see them. GGUF builds of one Qwen model can differ by whether they carry the multi-token prediction head, so check which build a tool pulled before comparing its speed with another’s. Where that head lives also varies by publisher, as our look at how MTP draft models are packaged found.
What is the verdict by memory tier?
For a 24 GB Mac, the safe choice is the Gemma 4 26B-A4B at 15 to 18 GB Q4, which delivers near-frontier scores. If you need the dense model specifically, Qwen 3.5 27B gives you more usable context headroom than Gemma 4 31B. The 31B dense model fits on 24 GB but requires a reduced context window of roughly 8,000 tokens to avoid swapping.
For a 36 GB to 48 GB Mac, Gemma 4 31B becomes viable. On our 48 GB M4 Pro it runs at a 64K context with headroom left and generates at about 11 tokens per second, slightly ahead of Qwen 3.5 27B’s 9.6 in the same test.
For a 64 GB and above Mac, the question shifts from whether to which precision. Gemma 4 31B at Q8 or even bf16 becomes possible. At bf16, the model occupies 58 GB and delivers reference-quality outputs. Qwen 3.5 122B-A10B at 4-bit also fits, requiring roughly 75 GB. The 122B MoE activates only 10 billion parameters and scores higher than either 27B or 31B model, but it demands a machine with 128 GB or more to leave room for context and the operating system.
The software stack matters too. Ollama supports both models equally well on Apple Silicon using Metal acceleration. MLX runs both families natively, and its 4-bit format for Gemma 4 31B is 2 GB smaller than the GGUF Q4_K_M variant, which can be the difference between fitting in memory and swapping on a 32 GB machine.
Neither model is universally faster or universally smarter. Gemma 4 31B is the stronger model for reasoning and agentic workflows on Macs with 48 GB or more of unified memory. Qwen 3.5 27B is the better choice for 24 GB to 36 GB configurations where context headroom matters more than the top benchmark scores. The unified memory advantage is real. The right pick depends on where your Mac sits in the memory bandwidth stack. For the wider field beyond these two, see our roundup of which local LLM to run in 2026.
Since this comparison, Gemma 4 31B has turned up somewhere unexpected: the second and third place entries in the first ARC-AGI-3 milestone both ran it locally. Here is what it does with an ARC-AGI-3 board on this stack.