Almost every privacy claim you have ever read is a promise. “We never sell your data.” “Your inputs are not used for training.” “Everything is encrypted.” These might all be true. You cannot check any of them. You read the sentence, you decide whether to trust the people who wrote it, and you move on. That is not privacy. That is faith.
Local AI changes the kind of claim you get to make. When the model runs on your own machine, “your data never leaves” stops being a sentence about intentions and becomes a fact about architecture. Nothing is being trusted. There is simply nowhere for the data to go. For a business that handles client material, that fact can be written down, tested and handed to the client as evidence.
What is the difference between asserted and demonstrated privacy?
There are two completely different things hiding under the same word.
Asserted privacy is a policy. Someone tells you what they do and do not do with your data, and you take them at their word, because the system runs on their servers and you cannot see inside it. Even an honest vendor can only offer you an assertion. The data left your machine; what happens next is out of your hands by definition.
Demonstrated privacy is something you can watch. The model runs locally, and you can open the network monitor and see no outbound traffic while it works. You can pull the network cable and watch the tool keep answering. The claim is no longer “we promise.” It is “look.” One of these you have to believe. The other you can check. It is the same instinct behind the way we check any AI tool before adopting it: prefer the thing you can verify over the thing you are asked to take on faith.
What happens to your code in a cloud AI tool?
Every AI coding assistant that runs through a cloud API makes copies of your source code. The copies are temporary in some cases and persistent in others, but in every case the code leaves a machine you control and travels across a network to infrastructure you do not.
GitHub’s own documentation says Copilot inline suggestions combine the code around your cursor with snippets from other open tabs in the editor and send the result to a large language model as a prompt. A credential sitting in an open tab can travel to a third-party server with that prompt. For a developer working in a monorepo with configuration files, credential stubs and database schemas, that is a larger exposure than the line being typed.
In March 2026, GitHub announced that interaction data from Copilot Free, Pro and Pro+ users would be used to train its AI models unless users opted out, according to the company’s privacy update. Private repository code being worked on falls within the scope of the policy. For those plans, interaction data including code snippets, accepted outputs and surrounding file context can be retained and used for training from 24 April 2026. The opt-out is a user-level setting, not an organisation-level one, so a single team member who does not disable it could expose proprietary code even if the rest of the team opted out.
GitHub’s Copilot plans page, read on 17 October 2026, draws the line by plan type. For Business and Enterprise it says GitHub “does not use either Copilot Business or Enterprise data to train its models”, that prompts and suggestions from IDE chat and code completions are not retained, and that prompts through other access are kept for 28 days.
Other tools work on the same pattern. Cursor offers a privacy mode toggle, but it is a policy control backed by terms of service, not a technical guarantee that can be verified from the client side. Codeium, which powers Windsurf, builds a local index and sends retrieved context to its inference servers in cloud mode; only its self-hosted enterprise tier keeps code off external servers.
How do AI coding tools expose more than you expect?
Research published by the Cloud Security Alliance in April 2026 identified three converging threat vectors in AI coding environments: prompt injection attacks targeting coding assistants, supply chain compromise through skill and extension marketplaces, and source code and credential leakage through AI tool interactions.
The report found that AI-assisted commits carried a secret leak rate of 3.2 percent compared to a 1.5 percent baseline across all public commits. Secrets related to AI services showed an 81 percent year-over-year increase, with 1.27 million AI service secrets leaked in 2025. For agentic development, 24,008 unique secrets were found exposed in Model Context Protocol configuration files, with 2,117 confirmed valid at the time of discovery.
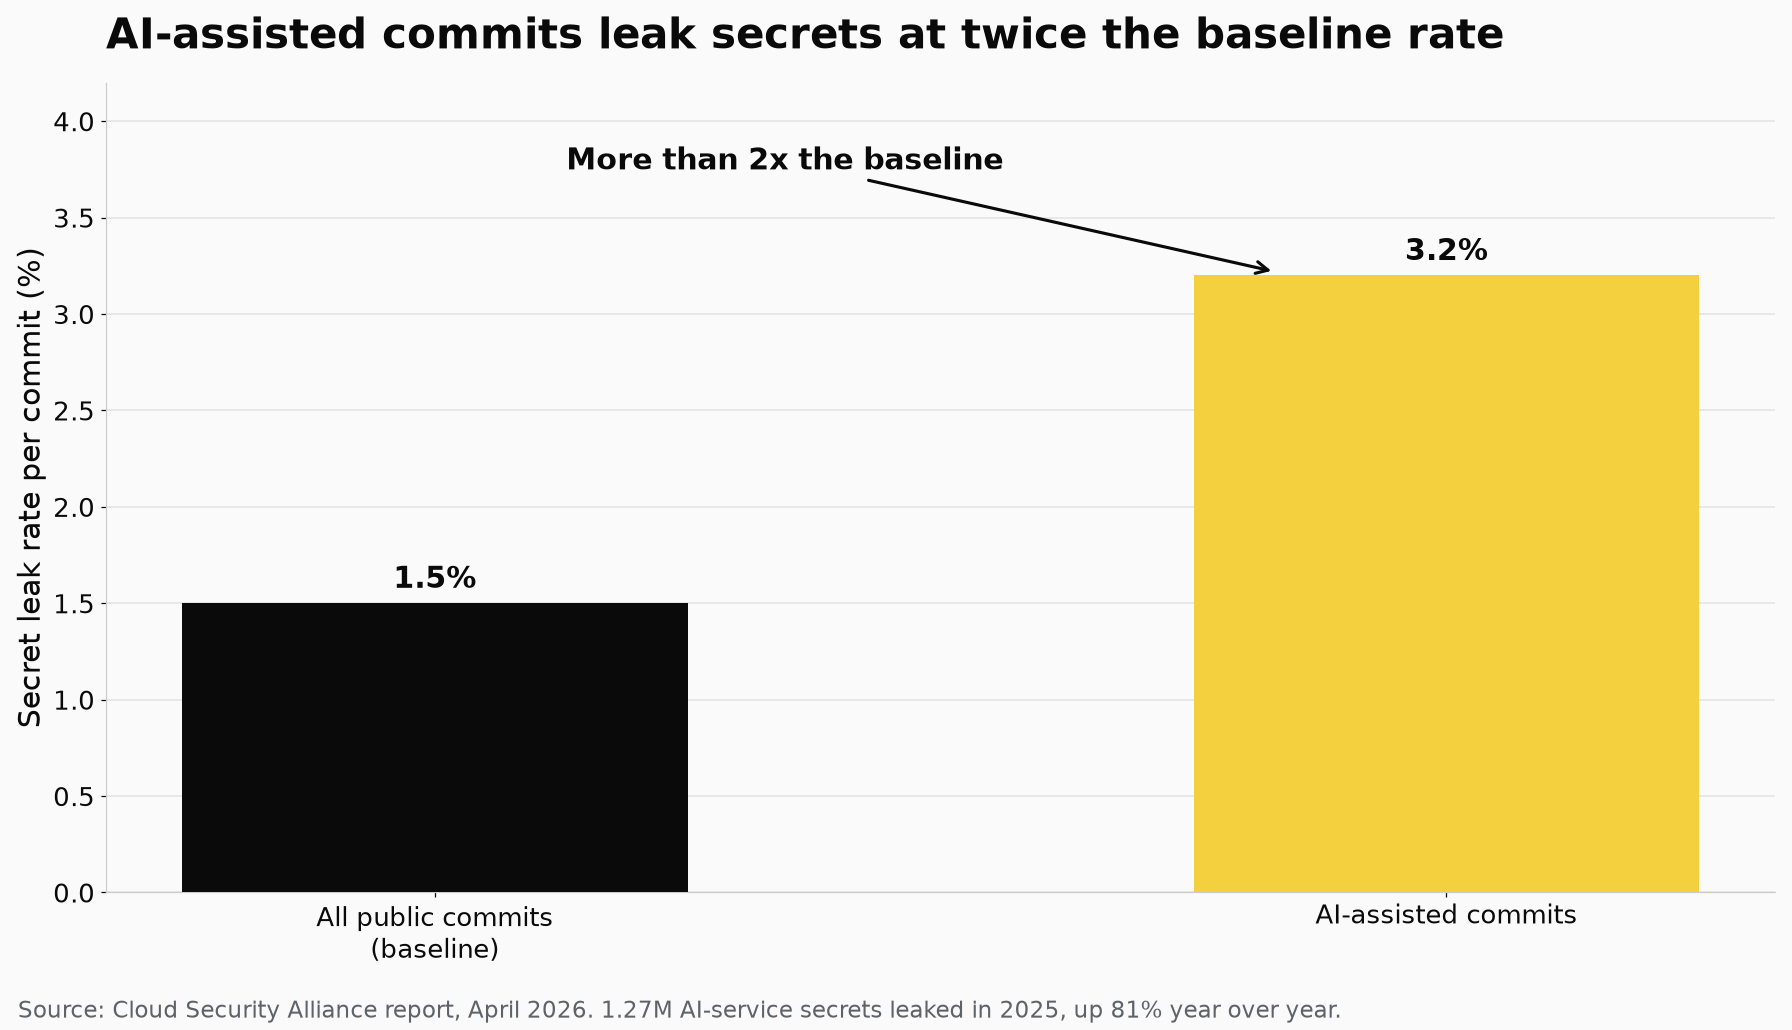
Cloud Security Alliance, April 2026: secrets appear in AI-assisted commits at more than twice the baseline rate.
The report also documented vulnerabilities in the tools themselves. CVE-2025-55284, affecting Claude Code prior to version 1.0.4, allowed injected prompts to read .env file contents and exfiltrate them via DNS subdomain encoding, a technique that bypassed network egress monitoring. Three additional CVEs were found in Anthropic’s official Git MCP server, where path traversal and argument injection flaws exposed repository data. None of these required sophisticated access. They activated on repository clone or workspace open, before any user interaction.
How can you prove a local model sends nothing?
The small, concrete version of the whole argument goes like this.
Run a local model through something like Ollama on your own machine. Open whatever your system uses to show network activity. Then give the model a prompt full of things you would never paste into a website: a client’s numbers, a private draft, a transcript of a real conversation. Watch the network indicator while it answers.
It stays at zero. The model thinks, the answer appears, and nothing went out. That single observation does more than any privacy policy ever could, because you did not have to trust anyone to get it. You saw it. Repeat it with the network cable physically unplugged and the result is the same: the model keeps working, because the computation never needed the network in the first place.
The tools to watch this are ones you already have. On a Mac, Activity Monitor has a Network tab showing bytes in and out per process, and a firewall like Little Snitch prompts on any outbound connection that a local model never triggers. Run the same check on the cloud tool you are comparing against and the contrast is immediate: its indicator lights up the moment you hit send.
What a local setup removes is specific. A cloud coding assistant creates four exposure surfaces: the vendor backend where prompts and outputs are processed, the vendor’s safety classifier metadata that may inspect your content, the local client cache that stores session transcripts in plaintext, and the backup snapshots that capture those transcripts indefinitely. A local tool has one surface, the local machine, and that surface is under your control.
What can you actually tell a client about privacy?
This is not only about how you feel. It is about what you can honestly tell a client.
“We take your privacy seriously” is what everyone says, and clients have learned to discount it, because they have heard it from companies that turned out not to. “Your data never leaves this machine, and here is the architecture that makes that true” is a different kind of statement. It is checkable. You can show the setup. You can explain that there is no endpoint, no upload, no third party in the loop, because the computation happens where the data already lives.
That difference has commercial weight. For a business handling client material, demonstrated privacy is not a compliance checkbox, it is part of the pitch: the work happens on a machine we control, which is also why we moved our daily AI work off paid cloud tools. A promise asks for trust. A fact offers proof. Proof is the thing you can put your name on. For organisations under frameworks such as GDPR, HIPAA or SOC 2, a cloud tool may offer a Data Processing Agreement and a zero-retention commitment, but those are contractual promises. The compliance question shifts from “what does the vendor commit to” to “what leaves the machine.”
Picture the concrete handoff. A client sends a folder of sensitive documents to summarise. With a cloud tool, your honest answer is that the files will be uploaded to a third party under their terms. With a local model, your honest answer is that the files never leave the machine in the room, and you can show it on the spot. One of those answers wins the kind of work where confidentiality is the whole job.
Local AI privacy evidence for clients: what to capture and hand over
A client who asks for proof needs more than a screenshot of a quiet network graph. The useful pack answers two separate questions, because local AI privacy has two parts: does the model send the work anywhere, and does the software around it report anything home. Our own captures showed why the second question matters. When we pointed OpenJarvis’s analytics host at a listener on our test machine, exactly one request left per chat session, carrying counters and no prompt text; with its analytics switch off, zero requests left. OpenCode initialises Sentry reporting at startup, and none of its 41 disable flags turns it off. Both results are in OpenCode vs OpenJarvis. The model was local in both cases. The software was not silent in both.
The steps we follow, and what goes in the pack:
- Record the setup: the machine, the app and its version, the model file, and the date.
- List open connections while a real prompt runs, for example with
lsof -i -P -nin Terminal or a firewall log such as Little Snitch, and save the output. - Repeat the same prompt with the network unplugged and note that the answer still arrives.
- Check each app’s own telemetry separately, and save any config change that switches it off.
What a business can show a client is a one-page statement built from those files: what was tested, on which date, which connections were seen, and what the statement does not cover, such as disk encryption and backups. It goes stale with each app update, so date it and rerun it when the software changes.
Should a business pay for a cloud coding plan or run AI agents offline?
For a team, the choice is between a cloud plan whose terms protect the code and a local setup where the code never leaves. The first decision is a policy one. If developers use personal Copilot accounts on company code, the company’s protection rests on each person’s settings. Moving everyone to an organisation plan puts the terms under one contract, but the terms are still a promise rather than a property of the system.
Running AI agents offline takes the vendor out of the question. The cost is capability on the hardest tasks and the work of keeping a local model running. A team does not have to pick one route for everything: local by default and cloud by deliberate exception can be written into policy repository by repository, with client or regulated code kept on the offline side.
Does local AI make you completely safe?
Local does not make you automatically safe, and it would be dishonest to imply it does. The data still sits on a machine, and that machine can be lost, stolen, unpatched, or carelessly backed up to somewhere less private than you think. Local AI removes one whole category of exposure, the data leaving your control over the network. It does not remove your responsibility for the machine itself: disk encryption, backups, access control, and patching are still yours to handle. The reassuring part is that these are old, well-understood problems with known answers, unlike the open question of what a vendor does with your data once it has arrived on their servers.
There is a licensing dimension too. “Runs locally” and “open” are not the same promise, a distinction worth understanding before you build on a model, which we pull apart in why open weights is not open source. Demonstrated privacy is a strong claim, not a complete one.
But it is the strongest claim most teams can make, and almost nobody is making it. The bar is not “trust us.” The bar is “watch the indicator.”
How do you switch to a privacy-first workflow?
The move from cloud coding assistants to a local setup takes about an hour. Install Ollama, pull a coding model like Qwen2.5-Coder or DeepSeek-Coder, and point your AI agent tool at the local endpoint. The agent connects to that endpoint the same way it would connect to OpenAI or Anthropic, but the request never reaches an external server. Most local-first tools detect Ollama automatically and configure themselves on first launch. For VS Code users, Continue with a local model gives privacy without leaving the editor.
Before you trust a tool, check two things. It should talk only to a local endpoint such as Ollama or LM Studio, with no telemetry on the side, and it should have a permission system for granular control over file and terminal operations. The telemetry test above is how you confirm the first.
The cloud does not have to disappear. In a week of coding with a local agent we kept OpenCode on a local Ollama model all week and made one deliberate trip to a cloud model for a single hard problem, then switched straight back. The default is local, the cloud is the exception, and the developer controls the routing. After the hardware is bought, the cost is zero per token.
Run a local model with the network monitor open. Send it something you would never paste online. Watch the zero hold. The proof takes about a minute, and once you have seen it you will never quite trust the promise version again. It reframes privacy from a sentence you have to market into a fact you can simply show, and that is a far easier thing to stand behind.
What happens when a local tool reports home anyway is in OpenCode vs OpenJarvis. Where StrideNote draws the line is set out in AI privacy and data control.